10 Best Nemo-Q Alternatives in 2026
Image File
Original HTML

See How WaitWell Works

Take a quick, self-guided tour

WaitWell recognized in Canada’s 2026 Top Growing Companies ranking. Read more

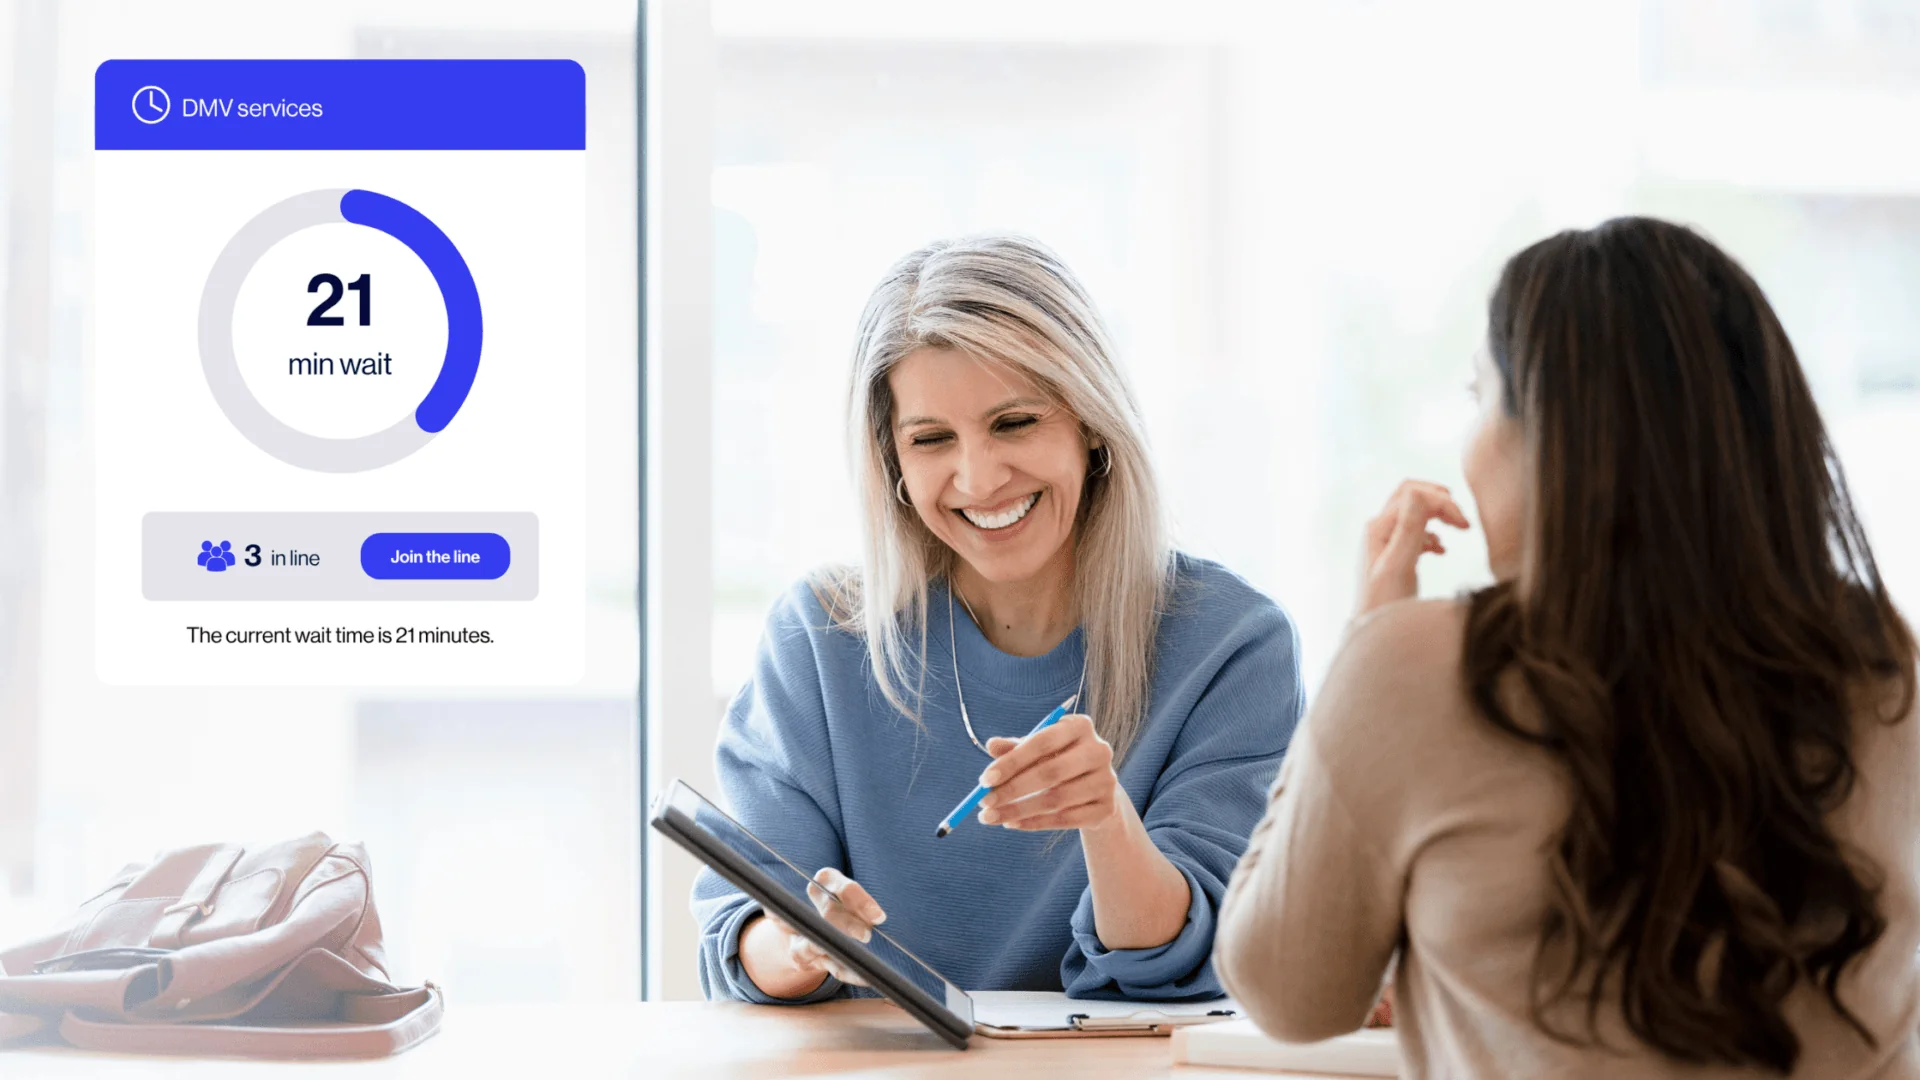
We evaluated 10 Nemo-Q alternatives across feature completeness in the published plan, accessibility and security documentation, native integrations and API access, unified walk-in and appointment management, self-service administration, multi-location configurability, product momentum, and independent review evidence.

Our findings show that WaitWell is the closest cloud-first match for public agencies, universities, and health systems that have outgrown Nemo-Q’s tiering model, where SMS notifications, appointment scheduling, mobile queuing, multi-language service, and skill-based routing all sit above the published entry plan, and that want those capabilities as standard alongside published SOC 2 Type II and HIPAA documentation a procurement file can actually cite.

For buyers whose needs are different in shape, several Nemo-Q alternatives are worth evaluating: Qtrac offers US agencies a GSA purchasing path from a vendor with four decades in queue management, Qminder publishes its pricing openly and is built around walk-in service analytics, Qmatic remains the reference point for hardware-integrated enterprise deployments, and QLess carries the longest continuous track record in government and higher education virtual queuing.

This guide is built for DMV and county office supervisors, one-stop directors, registrars, health system operations leaders, and the procurement and IT teams supporting them, who are re-evaluating an incumbent Nemo-Q deployment in 2026 and need a comparison that stands up inside an evaluation file.

Nemo-Q has been in queue management for more than forty years, operates from McKinney, Texas, and runs public counters that have worked reliably for a very long time. Its US-based support team is a genuine asset, and the tickets print.

The organizations that start looking elsewhere are usually long-tenured customers rather than new evaluators, and their frustration is rarely about reliability. It is about what the platform does not publish and what the entry plan does not include.

The points below are drawn from Nemo-Q’s own published pricing page and public materials as of August 2026. They are not commentary on whether the system works, because for its original design purpose it does.

Nemo-Q publishes an Essentials plan at $290 per month, which is more transparency than several competitors offer and deserves credit.

The plan is genuinely generous in some dimensions. It includes unlimited users, unlimited visitors, unlimited service queues, and unlimited email notifications with no hidden setup fees, plus digital signage capability, real-time reporting, data and analytics, and automated workflows.

What it covers is one location and ten workstations, and the notifications are email only. A county office with three branches, or a university one-stop running fifteen advising desks during registration week, is above that ceiling on day one. The published price is rarely the price that organization will pay.

This is the constraint that most often triggers the search, because these are not advanced features for a public counter. They are the baseline.

On Nemo-Q’s published pricing, SMS capabilities, appointment scheduling, multiple languages, and skill-based routing begin at the quote-only Flex tier. Mobile queuing, meaning check-in by phone or QR code, appears only at Enterprise, so it is absent even from Flex. Each of these also appears separately on Nemo-Q’s own add-ons list alongside text messaging and custom integrations.

A DMV that needs residents to check in from a phone, receive a text when their turn approaches, and be routed to the right examiner by skill is buying at least the Flex tier and probably Enterprise. A clinic serving a multilingual population is in the same position.

Organizations searching for alternatives are usually looking for platforms where the capabilities their job requires are included in a plan with a number attached to it.

Nemo-Q’s published tier list places API support, custom integration capabilities, and security log and audits at Enterprise only.

Public materials reference generic CRM and POS integration, but there is no published named connector for Microsoft 365 or Outlook, Google Calendar, Teams, Salesforce, Ellucian Banner, PeopleSoft, Workday Student, any EHR, or SAML single sign-on through Okta or a comparable identity provider.

For a registrar syncing advisor calendars, a clinic writing visit data back to an EHR, or an IT team that requires SSO before anything reaches a public counter, that combination is a hard stop. It is one of the most common reasons evaluators shortlist platforms with documented, pre-built connectors and API access that is not gated behind a price break.

Public sector and higher education procurement routinely requires a VPAT or Accessibility Conformance Report, a WCAG 2.1 AA conformance statement, and a vendor security attestation.

As of August 2026 we did not locate any of these published by Nemo-Q: no VPAT or ACR, no WCAG or Section 508 conformance claim, no SOC 2 Type II report, no HIPAA or BAA documentation, no ISO 27001 certificate, and no data residency disclosure.

Competing vendors in this category do publish some or all of these. For an agency responding to an ADA complaint, a university with a Section 508 obligation, or a health system running an annual security review, the absence of the paperwork is itself the disqualifier, regardless of how well the software performs at the counter.

Request these documents directly and see what comes back. This is a question with a fast answer.

The primary self-service asset on Nemo-Q’s support page is a downloadable remote-support executable, which tells buyers what the support model is. A technician takes control of a machine to make changes.

Support hours and SLA response targets are not published.

That model works when changes are rare. It becomes a bottleneck when an operations manager needs to add a service type, change a routing rule, or adjust a notification template and has to schedule a screen-share to do it. Teams that want to make those changes themselves, from a browser, on the same day, are searching for platforms with genuine self-service administration.

Nemo-Q publishes no release notes, no changelog, and no product roadmap. Its blog posts regularly through 2026 but carries no product announcements and no AI feature launches. The company’s own site footer still reads 2025.

Buyers benchmarking queue management systems against 2026 expectations, which now include AI-assisted wait time forecasting, conversational routing, natural-language operational reporting, and low-code workflow editing, cannot find evidence of forward motion to cite in an evaluation.

Independent review evidence is similarly thin. Nemo-Q’s listings on the major B2B review platforms show little to no rating or review volume, while category peers carry several hundred published reviews, and its case study page consists of customer quotes without dates or quantified results.

For an evaluation committee that has to justify either a renewal or a change, there is not much material to work with in either direction.

Before going deeper into the alternatives, it is worth being explicit about where Nemo-Q remains a sensible answer. The honest version of this guide is not that every Nemo-Q site should migrate.

If you run a single location with ten or fewer service workstations, your visitors are walk-ins who are physically present, and email notification is genuinely sufficient for your service model, the Essentials plan at $290 per month with unlimited users, unlimited visitors, and unlimited service queues is real value. Several platforms in this comparison would cost more for that specific profile once user counts are factored in.

If your operation is anchored in physical hardware that works, with ticket dispensers, counter panels, cashier and back-office displays, LED signage, and speech units already installed and functioning, the cost and disruption of replacing that estate may exceed the benefit of a cloud platform. Hardware that is doing its job is not a problem that needs solving.

If your organization values a long-standing relationship with a US-based support team that knows your configuration, and your change requests are infrequent enough that a scheduled remote session is not a burden, that continuity has real operational worth that a feature comparison will not capture.

If you are in a private-sector environment with no ADA or Section 508 exposure, no annual security attestation requirement, and no procurement rule demanding a VPAT, then the documentation gap that disqualifies Nemo-Q for public agencies simply may not apply to you.

For everyone else, and particularly for public agencies, universities, and health systems, the alternatives below are worth evaluating directly.

We evaluated each platform across eight weighted dimensions reflecting what we consistently hear from organizations re-evaluating an incumbent Nemo-Q deployment in 2026: whether the features a public counter needs are in the published plan, whether the vendor publishes the accessibility and security documentation procurement requires, and whether integrations and API access are available without a tier upgrade.

This guide is published on WaitWell’s own site, which means we have a commercial interest in its conclusions. We have worked to balance that by sourcing competitor data from vendors’ own pricing pages and published materials, marketplace listings, and user reviews on G2, Capterra, and TrustRadius, and by describing each vendor’s best-fit scenarios rather than framing every dimension as ranked competition.

Every claim about Nemo-Q in this guide traces to Nemo-Q’s own published pricing page, its public product pages, or named directory listings, checked in August 2026.
Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
6d8dc427ae27b790ad62cb05f262cc3b
Press Eligible
Yes
Press Eligible Reason
Manuelle Prüfung nötig. Risiko: MEDIUM. Flags: ['finance', 'numbers']. Stichprobe: False
Source Name
WaitWell
Original Summary

<p>The post <a href="https://waitwellsoftware.com/resources/articles/nemo-q-alternatives/">10 Best Nemo-Q Alternatives in 2026</a> appeared first on <a href="https://waitwellsoftware.com">WaitWell</a>.</p&gt;

Image URL
https://waitwellsoftware.com/wp-content/uploads/2026/09/Women-at-front-desk-with-wait-time-screen-.png
Source Node
Content Hash (SHA-256, erste 32 hex)
a7fc72324d1ed29056d39a8ec558e3b4
Cold chain monitoring systems explained: indicators, data loggers and IoT monitoring
Image File
Original HTML

Cold chain monitoring is often discussed as a choice between technologies.

Indicator or data logger? Connected or non-connected? Real-time visibility or information at receiving?

But for most logistics, quality and operations teams, the more useful question is broader:

What does our cold chain monitoring system need to help us see, document and act on?

A monitoring system is not simply the device traveling with a shipment. It is the combination of monitoring technology, shipment risk, hand-offs, documentation and the decisions teams need to make when something does not go as planned.

That is why the right cold chain monitoring approach may look very different from one shipment to another.

Think about the cold chain as a series of decision points

A temperature-sensitive product can pass through manufacturers, warehouses, carriers, distribution centers and receiving teams before reaching its final destination.

Every hand-off introduces another moment when someone may need to answer a question.

- Was the product kept within its acceptable temperature range?

- Did it experience excessive heat?

- Was it exposed to freezing conditions?

- Do we need to investigate what happened during transit?

- Is there still time to intervene before delivery?

The monitoring system should be designed around those decisions.

For a relatively simple shipment, teams may only need evidence at receiving that a defined temperature condition occurred.

For a more sensitive or valuable product, they may need a detailed temperature history.

For a complex or time-critical shipment, waiting until delivery may not be enough. Teams may need connected visibility while the shipment is still moving.

The goal is not to add the greatest possible amount of technology to every shipment. It is to create enough visibility to manage the specific risk.

Where temperature indicators fit into a cold chain system

Temperature indicators can provide a straightforward way to identify whether defined conditions occurred during a shipment.

For example, WarmMark QR can help monitor cumulative exposure above a specified temperature while supporting QR-enabled documentation.

FreezeSafe QR addresses a different risk by helping teams identify exposure below a specified temperature.

These types of solutions can be particularly useful when the most important outcome is a clear exception signal rather than a complete record of every temperature reading.

They can also support workflows where multiple people interact with a shipment. QR-enabled documentation can help capture information at selected points without requiring every user to download and interpret a complete data file.

What if both upper and lower temperature limits matter?

Some products are vulnerable in both directions.

A shipment may need protection from excessive heat while also remaining above a minimum temperature.

In those situations, monitoring only one side of the acceptable range can leave an important gap.

ColdChain Complete can be relevant where both upper and lower temperature thresholds need to be monitored on the same product or shipment.

This is less about adding another technology category and more about matching the monitoring approach to the actual stability range of the product.

If both heat exposure and freezing can compromise the shipment, both risks need to be visible.

When the shipment needs to tell a fuller story

An exception indicator can tell a receiving team that something happened. Sometimes that is enough. Sometimes the next question is immediately: When did it happen and for how long?

That is where electronic data loggers become more useful.

MaxiLog Data Loggers can record temperature measurements over time, creating a history that teams can review after or during the shipment depending on the solution and workflow.

That added detail can support investigations, quality review and documentation when a simple exception signal cannot answer all of the questions involved.

A detailed record may be especially important when:

- Product sensitivity is high

- Shipment value justifies deeper review

- Quality teams need evidence of conditions across the journey

- Multiple excursions may need to be distinguished

- Decisions depend on the duration and timing of an event

The September article, QR indicator vs. data logger: how much shipment data do you actually need?, explores that specific decision in more detail. The broader point here is that data loggers occupy one level within a larger monitoring system.

When knowing at receiving is too late

Traditional monitoring often supports a decision after a shipment arrives. Connected monitoring changes the timing of that decision.

Instead of learning about a potential problem at receiving, teams can gain visibility while goods are still in transit.

That can matter when there is still something useful to do. A delayed high-value shipment may need rerouting. A temperature excursion may require escalation. A shipment approaching a critical destination may need additional attention before delivery.

Connected solutions such as SpotBot GL and SpotSee Go can support workflows where teams need remote visibility into shipment conditions.

The value of connectivity is therefore not simply that it produces more data.

Its value comes from moving the decision earlier.

If knowing about an event during transit allows a team to respond differently than knowing about it after delivery, connected monitoring may provide an operational advantage.

If no action can or needs to be taken before arrival, that additional connectivity may not be necessary.

A cold chain monitoring program does not need one technology everywhere

Large cold chain programs rarely consist of one shipment type, one risk profile or one operational workflow.

A company may ship:

- Lower-risk products on predictable domestic lanes

- Higher-value products through multiple international hand-offs

- Products vulnerable primarily to freezing

- Products with narrow upper and lower temperature limits

- Critical shipments where teams need visibility before delivery

Using the same monitoring approach for every shipment can therefore create either too little information for high-risk movements or unnecessary complexity for lower-risk ones. A more scalable approach is to define monitoring levels.

For example, one shipment profile might require a simple visual or QR-enabled indicator. Another might require a complete temperature history. A third might justify connected monitoring because the cost of identifying an issue too late is significantly higher.

The technologies can coexist within the same cold chain program.

The important part is establishing clear criteria for when each level is used.

Build the monitoring approach around risk, workflow and response

When evaluating a cold chain monitoring system, it helps to look beyond the device itself.

Consider the entire workflow.

Product sensitivity

- How narrow is the acceptable temperature range?

- Can both heat and freezing affect product condition?

- How much exposure can the product tolerate before further assessment is needed?

Shipment value and criticality

- What is the consequence of losing or delaying the shipment?

- Would additional visibility materially change how the team manages that risk?

Hand-offs

- How many organizations or locations interact with the shipment?

- Does each hand-off create a need to document condition or verify that the shipment can continue?

Timing of the decision

- Does the team only need information at receiving?

- Or could knowing earlier allow someone to intervene?

Documentation requirements

- Is a simple visible result sufficient?

- Does the organization need digital documentation?

- Is a detailed historical record required for quality review or investigation?

Program scale

A monitoring approach that works for a small number of critical shipments may be difficult to manage across thousands of routine shipments.

The system should support both the level of risk and the practical realities of the operation.

The best monitoring system is the one that supports the next action

Cold chain monitoring is most valuable when the information collected leads to a clear decision.

An indicator may tell a receiving team to hold a shipment for review.

A data logger may provide the history needed to investigate whether an excursion affected product condition.

Connected monitoring may allow a logistics team to act before the shipment reaches its destination.

Those are different levels of visibility serving different operational needs.

The question is not whether indicators, data loggers or IoT monitoring are universally better.

It is whether the information each provides is appropriate for the risk, workflow and response associated with a particular shipment.

Frequently asked questions about cold chain monitoring systems

What is a cold chain monitoring system?

A cold chain monitoring system is the combination of technologies and processes used to observe, document and manage temperature conditions as temperature-sensitive products move through storage and transportation.

Depending on the application, that may include indicators, electronic data loggers, connected monitoring solutions or a combination of technologies.

Do all cold chain shipments need a data logger?

No. A data logger is useful when teams need a detailed history of temperature conditions over time.

If the operational decision only requires knowing whether a specified condition occurred, an indicator may provide sufficient information with a simpler workflow.

When is IoT monitoring useful in the cold chain?

Connected or IoT monitoring is most useful when having shipment-condition information during transit can change what the team does.

This may include high-value, time-sensitive or complex shipments where early awareness can support intervention, escalation or other action before delivery.

Can one shipment need both heat and freeze monitoring?

Yes.

Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
5e9a39dea90631600418e03ef4712f3b
Press Eligible
Yes
Press Eligible Reason
Explains cold-chain monitoring technologies and workflows for logistics and quality teams, including product examples.
Source Name
Spot.See
Original Summary

<p>Cold chain monitoring is often discussed as a choice between technologies. Indicator or data logger? Connected or non-connected? Real-time visibility or information at receiving? But for most logistics, quality and operations teams, the more useful question is broader: What does our cold chain monitoring system need to help us see, document and act on? A [&#8230;]</p>
<p>The post <a href="https://spotsee.io/blog/cold-chain-monitoring-systems/">Cold chain monitoring systems explained: indicators, data loggers and IoT monitoring</a> appeared first on <a href="https://spotsee.io">SpotSee</a>.</p&gt;

Image URL
https://spotsee.io/wp-content/uploads/2026/10/shutterstock_2706193101-scaled.jpg
Source Node
Content Hash (SHA-256, erste 32 hex)
dd0359734361ecac8994548c3ffd5ce4
The Identity Compromises You Aren't Seeing
Image File
Original HTML

The Identity Compromises You Aren't Seeing

Every time a new business considers working with Wirespeed, we look at their previous 90 days of detections together to get a feel for what's been happening and if anything was missed.

What we often see is a surprise to some businesses: suspicious logins on accounts with multi-factor authentication (MFA) enforced, going back weeks, that existing tools never surfaced. These are real sessions on real employee accounts from places those employees have never been.

The sessions typically aren’t flagged because the authentication evidence is clean on the surface: valid credentials, a satisfied MFA prompt, and a valid issued session. This is what identity compromise looks like, and it can be difficult to spot because the details are out of place.

Why stolen sessions look like strong authentication

When a user authenticates, the identity provider issues a session token. The browser stores it and presents it on every request afterward, so the user isn't asked to log in again. The token is proof that authentication already happened, honored until it expires.

A session token asserts how the user proved themselves and carries the authentication context that created it. It’s issued to one browser on one device and isn't designed to travel, but nothing in the exchange prevents the token from being replayed somewhere else, so when an attacker steals a live session, the assertion comes along with it.

A stolen session not only evades controls but also presents as one of the strongest authentication events in the tenant. For example, when Entra ID Protection detects something anomalous — unfamiliar location, new ASN, odd device — it emits a risk signal that turns into an MFA prompt. Satisfy the prompt, and the sign-in risk is marked resolved (depending on configuration).

To an analyst scrolling a queue, this looks like the system caught something, challenged it, and the challenge passed. The platform may not reliably distinguish a stolen session from a legitimate one because the proof of strong authentication is real — it just isn't attached to the person it was issued to anymore.

How attackers steal the session

The prevailing method is an adversary-in-the-middle (AITM) attack. The attacker stands up a reverse proxy that wraps the real login page and sends a phishing lure pointing at it. The victim clicks through, sees the genuine sign-in screen, and authenticates normally, password and MFA prompt included. The proxy sits in the middle of that exchange and copies the credentials and the session token as they pass.

None of this requires the attacker to be present. They build the lure, send the phishes, and come back later to collect whatever sessions have accumulated in the meantime. This is at least partially why the compromised logins we discover are often weeks old before anyone looks at them.

Device code phishing is the tactic we're starting to see more frequently. (Think of a college student adding their smart TV to a parent’s Netflix account using a short alphanumeric code.) The attacker starts a device authorization flow to generate a code, then sends the victim both the code and a real Microsoft URL that will grant the attacker access. The victim signs in at Microsoft's actual page (because that’s genuinely where they are), and the attacker collects the session token behind the scenes from Microsoft. There’s no proxy to detect and no lookalike domain to block.

Sessions are also stolen directly off the endpoint. Infostealer malware can pull live session cookies out of browser profiles, including on unmanaged or personal devices. Malicious browser extensions do the same from inside the browser the employee uses every day. A stolen password is mitigated by MFA; a stolen session token was minted after MFA already succeeded.

Hiding in ordinary traffic

Knowing a session can be stolen doesn't help if the replayed login looks like it came from the employee's own neighborhood. Attackers rent access to residential proxy networks, which route traffic through real consumer devices on ordinary home internet connections.

In March, the FBI warned that buyers of these services can pick an exit address by country, state, and city, and directly named account takeover as a use case: obtain an IP address in the victim's city, sign in with stolen credentials, and the activity is far less likely to be flagged.

Microsoft has documented the same tactic, specifically in business email compromise events, where attackers buy residential IP space matching the victim's location to circumvent impossible travel alerts.

Mobile proxies are a newer iteration, one we're watching closely. Traffic exits through cellular carrier address space, either via malicious mobile apps or apps that pay consumers to share their mobile bandwidth plan. Here, the session presents as an employee checking email on their phone.

How a quiet login can escalate

For years, much of this access went nowhere. If the compromised employee wasn't an administrator or couldn't move money, attackers poked around, found nothing worth the effort, and moved on (or used the victim to forward more phishing attempts).

But attacker attention isn’t as expensive anymore. Talos recently identified ARToken, a phishing-as-a-service platform that automates the entire process: token management, inbox rule manipulation, and keyword monitoring across every compromised mailbox for the words that signal money moving. Reconnaissance that used to require a human is now a simple query.

When evaluating stolen access costs nothing, no account is too unimportant to evaluate. Any email account can be monetized, regardless of what that employee can reach, because the inbox itself is the weapon. An internal email from a compromised colleague's account may clear every filter a business owns. It may bypass perimeter-based controls and exploit a trusted relationship that some security controls do not inspect.

Inbox rule manipulation is one of the most reliable indicators of compromise available, but these indications arrive late.

We’ve clocked attackers moving from account takeover to sending an internal phish in just 47 seconds. That’s a highly automated attack, not a person reading a stranger's inbox and deciding what to do with it. What follows is unfortunately familiar: Someone in finance receives a note from a colleague they email every week, about an invoice they were already expecting, with updated payment details.

Then, the attacker may hide the conversation. A new inbox rule can send replies from that finance colleague straight to an unmonitored folder, and the employee whose account is sending the messages never sees the thread. The fraud runs inside a real mailbox, in a real conversation, with the account owner reading a version of their inbox that has been edited for them.

Inbox rule manipulation is one of the most reliable indicators of compromise available, but these indications arrive late. A rule exists to conceal messages that have already been read and replies that are already coming, so by the time one appears the attacker has been in the mailbox for a while and has likely already sent something.

Containment that doesn’t wait

Catching an identity compromise means treating a successful login as the start of the question, rather than the end of it.

Wirespeed learns where your employees sign in from, on what devices, at what hours, and what the account does once someone’s inside. Departures from that pattern are the signal, and the picture has to be wider than location: a device that doesn't match the person, a session behaving nothing like the employee it belongs to, a new inbox rule quietly filing a colleague's replies where nobody will read them.

With Wirespeed, the verdict and containment happen together: full investigations on signals from 85+ integrations across endpoint, identity, network, SaaS, and cloud complete in milliseconds.* If an identity compromise is suspected, active sessions are terminated, and the employee is forced to reauthenticate. The account is locked down in milliseconds without a human bottleneck.

An attacker holding a valid session token doesn't need to break anything. They need enough to read the inbox, learn who approves the payments, and send an email. Every second that session stays alive cedes the advantage to the attacker. The question is how long you’re willing to wait.

LIGHTNING-FAST SPEED. LASER PRECISION.

Try Wirespeed Today

Start your free 30-day trial >

This article originally appeared in the September 2026 edition of the Milliseconds Matter Newsletter. Subscribe to the newsletter to receive future editions directly in your inbox as we explore what happens when cyber threats move at machine speed and how defenders can keep up.

Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
9a399669290860be523c013ebaea9112
Press Eligible
Yes
Press Eligible Reason
Manuelle Prüfung nötig. Risiko: MEDIUM. Flags: ['numbers']. Stichprobe: True
Source Name
Coalition Inc
Original Summary

Catching an identity compromise means treating a successful login as the start of an investigation, rather than the end of it.

Image URL
https://images.ctfassets.net/o2pgk9gufvga/5OQGJJMvXG741c0EZmz6Lt/6406a7c94b4db2d105d3037381841e97/Wirespeed-Blog-Identity-Compromise.png
Source Node
Content Hash (SHA-256, erste 32 hex)
1ee3653986e6f4498307a03455be2b8c
Designing Security for the People Who Have to Live With It
Image File
Original HTML

Designing Security for the People Who Have to Live With It

Our primary goal as a cybersecurity organization is simple: make the secure path the easy path.

Anyone who tells you security doesn't introduce friction is lying. It’s rare to add protection without adding cost somewhere, and the cost is usually paid in someone else's time and attention.

The best security program is the one nobody notices. Not because it isn't there, but because it seamlessly integrates into the organization and supports, rather than hinders, getting the job done. At its best, an effective security program can be a risk-enabler, which opens the door for more opportunities than it closes off.

I've spent 25 years in InfoSec, building products, getting paid to break them, and defending companies. For the last five years, I’ve dedicated my career to protecting Coalition and recently stepped into the role of Chief Information Security Officer. Fittingly, our mission here is to protect the unprotected.

Coalition’s mission points inward as much as outward. After all, we can't credibly protect other companies without protecting our own, and executing that mission starts with how we build and maintain trust within our own walls.

Why frictionless security wins

The Information Security team must play a delicate balancing act and avoid squandering its mandate. People want to do the right thing for security, but their most important goal is to get their job done and have a positive impact on the business. Heavy-handed security can turn goodwill into circumvention. People tend to find the path that lets them finish their work, and the workaround is almost always less protected than the one they avoided.

My team operates as if we have a basket of tokens. The tokens are the organizational trust we’ve been given, and we have a finite amount to spend on security. Every control we implement costs us tokens, some more than others. It’s easy for a security team to feel all-powerful, but every high-friction rule burns through that trust.

We can't credibly protect other companies without protecting our own, and executing that mission starts with how we build and maintain trust within our own walls.

The discipline is spending deliberately: accepting friction where the risk genuinely warrants it and hunting for places where you can raise the bar and lower the cost in the same move. But deliberate spending isn’t the same as going easy.

The tokens exist to be spent, and hoarding them only benefits attackers. A control that was adequate two years ago may not be adequate today, which means the requirements we place on ourselves, and on the companies we depend on, have to keep improving. At Coalition, we expect a high standard from our vendors, and we hold ourselves to the same bar. There's no quarter from me on either.

The cost of saying no

Right now, the sharpest test of all this is AI. When a new category of tooling emerges, the instinctive security answer is to say no.

Saying yes opens the door to security risks that you can’t yet name. Saying no creates a risk that lands on somebody else — the team shipping slower, the function that can't automate — and never appears in a security report. Many security programs default to refusal, and refusal is often the more expensive choice. But an organization that falls behind its competitors by saying no to everything takes on risk just as surely as one that moves too fast. This is when being deliberate about spending your tokens will have the most positive impact.

The real work is engineering the yes: naming the specific exposure rather than the general unease, deciding which exposures are worth carrying, and getting leadership genuinely aligned on where the line sits. Coalition is well-positioned for these conversations because we see cyber risk from several angles at once. Our underwriting teams track how AI risk is emerging across a wide swath of businesses. Our incident responders are in the trenches, handling active events on real victims. Our entire organization is full of technologists who take things apart to understand them.

Saying yes opens the door to security risks that you can’t yet name. Saying no creates a risk that lands on somebody else and never appears in a security report.

When we weigh a new exposure, we reason from what we observe rather than what we imagine. Saying no is what you fall back on when you can't see well enough to say anything else.

Plan for controls to fail

No matter how strong your program is, you should be prepared. You can be the best driver on the road and still end up in an accident.

Every security leader should plan for controls to fail at some point and say so plainly to their executives long before anything happens. If you have let people believe a breach is impossible, you’ll inevitably struggle to get the time and money to prepare for one and find yourself explaining residual risk at the worst possible moment.

Planning for failure is what produces preparedness. If you accept that you’ll be breached at some point, decisions get made in advance:

- Who has the authority to pull a system offline?

- Who communicates with customers?

- What can the business live without?

- How do we keep operating when systems are down?

Those decisions are difficult to make under the pressure of a real incident, and the teams that make them beforehand are the ones better positioned afterward. To prepare, we run regular tabletop incident response drills and continually work to raise the bar. We may not be able to predict the exact event, but our practice gives us a framework we can use to respond effectively, if necessary.

Credibility is hard to build and easy to lose

As a security leader for a company that advises other businesses on managing cyber risk, I believe we’re answerable for how we manage our own risk.

Coalition has earned its standing in the cyber insurance industry, in part, because brokers and policyholders trust that our team knows what it’s talking about. Credibility takes years to build, but it only takes one bad day to lose it all. Integrity matters to me, and advice you wouldn’t implement yourself is the definition of bad advice.

The standard here isn't mine alone to take credit for. Security works as an enabler at Coalition because of an entire team that asks the same question before anything ships: What is this going to feel like to the person on the other end?

I feel fortunate to work at a place where I’ve never once had to argue that security matters. Our customers put their trust in us every day. Deserving that trust means being there on the day something goes wrong for them and having done the unglamorous work long before.

Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
6d1fccf1863e33e66a485934d90218cb
Press Eligible
Yes
Press Eligible Reason
Cybersecurity leadership insights from Coalition’s CISO, focused on enterprise security and risk management.
Source Name
Coalition Inc
Original Summary

Anyone who tells you security doesn't introduce friction is lying. Protection comes at a cost, and it’s usually paid in someone else's time and attention.

Image URL
https://images.ctfassets.net/o2pgk9gufvga/1X9lXDmqDCNEzo9ijBwNP2/5afb3029a3a2862af97ff250b9e35416/Coalition-Designing-Security.png
Source Node
Content Hash (SHA-256, erste 32 hex)
d87b22ac2e49c21da113e7f1d69c8c6c
Security Alert: Critical PHP Vulnerabilities Put Most of the Web at Risk
Image File
Original HTML

Security Alert: Critical PHP Vulnerabilities Put Most of the Web at Risk

Every few years, a vulnerability surfaces in software so deeply embedded in the internet that nearly every organization is affected at once. Heartbleed was one. Log4Shell was another. This time, it’s PHP2Shell.

The PHP project has released emergency patches for two critical vulnerabilities that let an attacker run code on a web server and take control of it without logging in. CVE-2026-109618 and CVE-2026-109619 both carry a CVSS score of 9.2.

Attackers can also use the vulnerabilities to read passwords, API keys, and other secrets straight from server memory. The flaws sit in PHP itself, not in any single application, so every website and web application built on PHP is potentially exposed.

Coalition urges every organization running PHP to patch immediately. Our threat intelligence team began observing exploit-related activities more than five hours before PHP released its fix, and activity has grown since. We expect these vulnerabilities to be exploited at scale.

Coalition sent an initial Zero-Day Alert to some policyholders running known vulnerable versions of PHP on October 20, prior to the public disclosure of the vulnerabilities. Our team will continue outreach efforts as the broader exposure of the vulnerabilities develops, and we will update this blog on an ongoing basis as new information becomes available.

UPDATE: On October 21, Coalition sent a Zero-Day Alert to all policyholders with PHP exposed to the internet and provided remediation guidance.

What we know

PHP powers roughly 7 in 10 websites whose server-side language is known and also runs many of the admin tools businesses use to manage firewalls, databases, phone systems and backups.

PHP published its advisory on October 21, a day earlier than planned after details leaked online, urging all PHP users to update immediately.

- CVE-2026-109618 is a remote code execution (RCE) vulnerability caused by how PHP handles running out of memory.

- CVE-2026-109619 is an RCE caused by leftover data from one web request being reused by the next.

Wiz Research, which found the flaws in collaboration with Calif and OpenAI, also showed that attackers can read sensitive data from server memory without taking over the server. That data can include passwords, authentication tokens, API keys, and certificates. The affected code dates back to PHP 5.4, released in 2012, so effectively every version in use today is vulnerable.

PHP says all installations that serve web requests are at risk, including PHP-FPM, Apache with mod_php, php-cgi, FrankenPHP, and LiteSpeed. It considers the risk highest for Apache with mod_php, where it has demonstrated a working exploit.

Neither CVE was on CISA's Known Exploited Vulnerabilities (KEV) list at the time of writing.

What Coalition honeypots are seeing

Coalition runs a global network of honeypots, decoy systems that record what attackers send across the internet. Between October 20 and October 21, our threat intelligence team tracked requests matching the patterns used to exploit the PHP2Shell vulnerabilities.

- Attackers moved before the patch: The first exploit-related requests reached our sensors at 08:00 UTC on October 21, more than five hours before PHP released its fix. Some referenced "p2shell," the name used by exploit tools now circulating online.

- Reconnaissance spiked just before the release: Between 12:00 and 13:00 UTC, requests for phpinfo pages jumped to 3,839, compared with about 100 in a typical hour. These pages (when exposed to the public internet) reveal a server's exact PHP version and configuration, which attackers use to pick targets.

- Activity jumped after the advisory: In the three hours after PHP's release, we logged 133 requests abusing the upload-progress feature these attacks rely on, compared with 28 in the hours before release.

- Attackers are moving from probing to exploitation: About 2.5 hours after the release, we saw the first requests built to trigger the out-of-memory flaw behind CVE-2026-109618.

These numbers are still small, which is typical in the first hours after disclosure. Attackers were preparing before a patch existed and began attempting exploitation within hours of initial disclosure. (We will update this section as more data becomes available.)

How widespread is the exposure?

PHP is reportedly used by 69.3% of websites whose server-side language is known. For context, WordPress, which runs on PHP, accounts for 39.6% of all websites on its own.

Most WordPress sites sit with hosting providers that will, at some point, roll out patched PHP builds. However, speed is of the essence. Those sites still need updating, but they rarely hold critical data and can usually be restored quickly. The bigger concern is everything else that runs on PHP.

Coalition data reveals exposure is spread across every PHP branch, not concentrated on the newest releases. A meaningful share of vulnerable assets run end-of-life versions (8.1 and older) that will not receive an official fix. These systems are often the hardest to patch and the easiest to forget.

Why the real risk goes beyond websites

Many of the tools businesses use to run their IT are built on PHP. These admin interfaces hold credentials, configuration, and control over critical systems. If one is exposed to the internet, a single request could give an attacker a foothold that leads to a much larger incident. Examples include:

- Database administration tools, such as phpMyAdmin and Adminer, which give direct access to business data.

- Firewalls and network appliances, such as pfSense and OPNsense, which hold VPN credentials and control network access.

- Backup administration consoles, such as Bacula-Web and Bareos WebUI. Attackers who reach backups can destroy or encrypt them, which makes ransomware far more damaging.

- IT monitoring and asset management tools, such as Zabbix, Nagios XI and GLPI, which store credentials for many other systems.

- Phone system admin panels, such as FreePBX, a common target for toll fraud and call interception.

These are the systems to find and patch first.

Recommended action

1. Find every PHP system

Inventory your websites, internal tools, and vendor appliances that run PHP, including copies bundled with control panels, such as cPanel and Plesk. Start with the admin tools listed above. Coalition Control policyholders can go to Assets → Technologies and search for PHP.

2. Update PHP now

Update to PHP 8.5.12, 8.4.27, 8.3.36 or 8.2.35 or later, then restart PHP-FPM or your web server so the new version loads. If you install PHP through a Linux distribution or hosting provider, apply their updated packages. Their version numbers may not match PHP's, so confirm with your vendor that the fix is included.

3. Deal with end-of-life versions

PHP 8.1 and older will not get an official patch. Upgrade to a supported version, or ask your vendor for a backported fix. Until then, take these systems off the internet.

4. Reduce exposure if you can't patch right away

Take PHP applications off the internet or put them behind a web application firewall (WAF). Cloudflare, Akamai, AWS, Fastly, Google Cloud, and other providers have prepared WAF protections for these vulnerabilities.

Then apply these temporary settings:

- Set session.upload_progress.enabled=0 in php.ini or your server configuration, then restart all PHP workers.

- Set memory_limit=-1 in a way applications can't override, and keep post_max_size low (8M, or 32M if your application needs uploads).

- On PHP 8.5, also set fatal_error_backtraces=0.

- If your application doesn't accept file uploads, block multipart/form-data requests at your web server or WAF.

These settings reduce risk but do not fix the vulnerabilities. Only updating does.

5. Check for compromise

Look for PHP processes starting shells or tools like curl or wget, new or changed files in your web root, and new cron jobs or user accounts. Because the attack happens below the application, app logs may show little. Wiz recommends also watching for:

- Web requests carrying file uploads followed by out-of-memory errors or a run of HTTP 500 errors

- Oversized or garbled session cookies (PHPSESSID) in server response

- PHP workers that crash or restart repeatedly without explanation

6. Report suspicious activity

Coalition policyholders who find signs of compromise should contact the Coalition claims team immediately.

Next steps

Coalition will continue proactive outreach to policyholders using PHP, monitor for exploitation, and update this guidance as new information emerges.

Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
7a9eb8954b8facc6942667b66590eecf
Press Eligible
Yes
Press Eligible Reason
Manuelle Prüfung nötig. Risiko: MEDIUM. Flags: ['numbers']. Stichprobe: False
Source Name
Coalition Inc
Original Summary

Coalition is actively urging all businesses using PHP to patch two critical vulnerabilities in software widely used across the internet.

Image URL
https://images.ctfassets.net/o2pgk9gufvga/8Hl3lbngZEzSHCOM3Qom4/32471db8e3f4d1d4bc2c221dce9c9b6a/Coalition-PHP.png
Source Node
Content Hash (SHA-256, erste 32 hex)
95a5a9b139b2f6a80ceacff0f36f1748
From 9,000 Agents to Real ROI: AI Agents vs. Workflows Explained
Image File
Original HTML

The enterprise has 9,000 AI agents.

Excellent.

What do they actually do?

That question has become the real measure of enterprise AI maturity.

Agent counts appear on dashboards, investor presentations, and transformation roadmaps because they signal progress. Yet an organization with hundreds of agents can still struggle to deliver measurable business outcomes if those agents solve problems that structured workflows could have handled more efficiently.

The conversation around enterprise AI has shifted from building more agents to building the right architecture. Oracle’s perspective on agents versus workflows reflects this shift. The value no longer comes from autonomy alone. It comes from knowing where autonomy belongs.

That distinction is where enterprise ROI begins.

What is the difference between agents and workflows?

A workflow executes a predefined sequence of business logic. An AI agent decides parts of that sequence while work is in progress.

Workflows thrive when business rules are predictable. They move invoices, validate records, route approvals, trigger integrations, and execute repeatable tasks with speed and consistency.

Agents earn their place when uncertainty enters the process. They interpret context, select tools, adapt to changing conditions, retrieve knowledge, and determine the next action without every decision being scripted beforehand.

Many organizations blur these boundaries by labeling every AI-powered capability as an agent. In reality, enterprise AI works as a spectrum. Scripted workflows, LLM-assisted workflows, reactive agents, and autonomous agents each solve different problems. Choosing the highest level of autonomy every time usually increases cost without increasing value.

Why are enterprises building too many agents?

Low-code AI platforms have made it remarkably easy to assemble working prototypes. Operationalizing them remains far more difficult.

Every production agent requires identity controls, governed data, observability, security, evaluation, cost monitoring, and human oversight. Oracle AI Data Platform addresses many of these foundational requirements by connecting enterprise data, business semantics, AI services, and governance into a unified architecture.

The challenge is rarely building an agent. The challenge is ensuring every agent operates against trusted business context and continues delivering value after deployment.

When does an AI agent actually create ROI?

A simple question helps separate architecture from hype.

Does the task require reasoning, or reliable execution?

If every decision can be documented before the process starts, a workflow usually provides the fastest, safest, and most economical solution.

Agents create value when context changes the outcome. Investigating supplier disputes, interpreting contract language, resolving complex customer requests, or coordinating actions across multiple enterprise systems are examples where reasoning becomes essential.

Enterprise AI should reserve autonomy for work that genuinely benefits from it.

What does this look like in Oracle environments?

Accounts payable offers a practical example.

Invoice capture, purchase order matching, validation, and approval routing follow structured business rules. Workflows remain the ideal architecture.

Exceptions tell a different story. Missing purchase orders, conflicting supplier records, tax questions, or incomplete documentation require information spread across ERP systems, contracts, emails, and enterprise knowledge.

Oracle Payables Agent illustrates this approach in practice. Routine activities such as invoice capture, matching, and validation remain inside deterministic workflows, while AI steps in to resolve exceptions that require context, judgment, and cross-system reasoning. The result is higher automation, lower operational effort, and AI applied only where it creates measurable value.

For organizations running Oracle Fusion Cloud Applications, Oracle Database 23ai, Oracle Integration Cloud, and Oracle AI Data Platform, this architecture enables governed AI that operates with enterprise context rather than isolated prompts.

How should executives evaluate every new AI agent?

Before approving another agent, leadership should ask:

• Which part of the process truly requires reasoning? 

• Which steps remain deterministic? 

• Which enterprise systems and data will the agent access? 

• How will quality, cost, and governance be measured? 

• Would a workflow deliver the same business outcome more efficiently? 

Strong AI programs measure business outcomes instead of deployment numbers.

Final thoughts

Every enterprise is capable of deploying thousands of AI agents.

Very few are capable of engineering an intelligent enterprise.

The difference has little to do with models. It comes down to architecture. Organizations that create lasting business value understand that workflows, agents, enterprise data, and governance are complementary capabilities, each solving a different class of problem. Intelligence belongs where reasoning improves the outcome. Everything else belongs inside well-engineered execution.

Oracle provides the enterprise platform that brings those capabilities together. AppsTek helps enterprises transform that foundation into governed, production-ready AI that strengthens the digital core and delivers measurable business value. Talk to our experts.

Frequently asked questions

Workflows follow a fixed sequence of steps. AI agents make decisions on the fly. Use workflows for predictable, rule-based tasks. Use agents when a task needs judgment or reasoning across systems.

Agent count is not a performance metric. Many of those 9,000 agents are likely doing jobs a simple workflow could do faster and cheaper. Enterprise AI maturity comes from outcomes, not headcount.

Ask one question: does this task need reasoning, or just reliable execution? If you can document every decision in advance, build a workflow. If the outcome depends on shifting context, build an agent.

Every agent in production needs identity controls, governed data, and human oversight. Skip that, and scaling past 9,000 agents just creates enterprise AI sprawl that's costly to run and hard to trust.

Oracle Payables Agent keeps invoice capture and matching inside workflows. It hands off only the exceptions, like disputed invoices or missing documentation, to AI agents. That split is the model for enterprise AI done right.

About The Author

Myrlysa I. H. Kharkongor is Senior Content Marketer at AppsTek Corp, driving content strategy for the company’s digital engineering services to enhance brand presence and credibility. With experience in media, publishing, and technology, she applies a structured, insight-driven approach to storytelling. She distills AppsTek’s cloud, data, AI, and application capabilities into clear, accessible communications that support positioning and grow the brand’s digital footprint.

Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
9ca1526ddc0335f4a90986858d1c5faf
Press Eligible
Yes
Press Eligible Reason
Enterprise AI architecture and Oracle products are discussed for business professionals, with substantive analysis despite promotional content.
Source Name
AppsTek Corp
Original Summary

<p>Table of Contents What is the difference between agents and workflows? Why are enterprises building too many agents? When does an AI agent actually create ROI? What does this look like in Oracle environments? How should executives evaluate every new AI agent? Final thoughts Summarize the article now The enterprise has 9,000 AI agents.  Excellent.  [&#8230;]</p>
<p>The post <a href="https://appstekcorp.com/blog/oracle-9000-ai-agents/&quot; rel="nofollow">From 9,000 Agents to Real ROI: AI Agents vs. Workflows Explained</a> appeared first on <a href="https://appstekcorp.com&quot; rel="nofollow">AppsTek Corp</a>.</p>

Image URL
https://appstekcorp.com/wp-content/uploads/2026/09/enterprise-has-9000-AI-agents-img.jpg
Source Node
Content Hash (SHA-256, erste 32 hex)
7e47f632ee6cd0b598b555cdfd0b45ab
A Complete Guide to Agentic AI Enterprise Search
Image File
Original HTML

Enterprise search has failed the same promise for three decades. Every generation of the technology claimed to help employees find what they need, and every generation left a meaningful share of the workforce searching multiple systems, asking colleagues, or simply redoing work that already existed somewhere in the organization. Generative AI has changed the economics of that problem, but not by making search better on its own. It changed the problem by giving enterprises a way to combine search with reasoning, and now, with autonomous action.

This guide covers the three technologies enterprises are being asked to evaluate together for the first time: enterprise search, retrieval-augmented generation, and agentic AI. Understood separately, each is well documented. Understood together, as a single evolving stack, they explain why so many organizations are rearchitecting how employees and AI systems find and use enterprise knowledge.

Why Enterprise Search Still Fails

The scale of the problem is well documented in current industry research. According to Gartner’s Market Guide for Enterprise AI Search, published in September 2025, 34 percent of employees struggle to find the information they need to do their jobs. Roughly 49 percent of workers now primarily rely on AI tools such as Copilot or Gemini for data discovery rather than traditional search interfaces, yet 36 percent of those AI tool users still report difficulty accessing relevant information despite that assistance.

Gartner forecasts that by 2028, 60 percent of organizations will deploy more than six enterprise AI search platforms across the business, and 60 percent of enterprise applications will have embedded AI search capabilities, up from roughly 20 percent today. The underlying shift Gartner describes is a move from information retrieval, returning a list of documents, toward information synthesis, returning a grounded, contextual answer.

Gartner also notes that no single approach dominates the category. Enterprises are pursuing search as a unified platform indexing content across many sources, in-application search embedded directly inside specific tools, and federated search that queries separate indexes without centralizing them, often combining more than one approach rather than standardizing on a single model.

That shift is exactly what retrieval-augmented generation was built to enable, and exactly what agentic AI is now extending further.

The Evolution of Enterprise Search

Keyword search matched query terms against an index and left interpretation entirely to the user. Semantic search introduced embeddings, allowing systems to match meaning rather than exact terms, but still returned a ranked list of documents rather than an answer. Retrieval-augmented generation changed the output itself: instead of a list, the system retrieves relevant passages and uses a language model to synthesize them into a direct, sourced answer. Agentic AI represents the current stage, where the system does not just answer a question but decides how to investigate it, which sources to consult, when to retrieve again, and in some deployments, what action to take once it has an answer.

Each stage did not replace the one before it so much as absorb it. A modern agentic search system still depends on the indexing and ranking techniques keyword and semantic search perfected; it simply adds a reasoning and orchestration layer on top.

How RAG Actually Works

Retrieval-augmented generation grounds a language model’s response in retrieved enterprise content rather than relying solely on what the model learned during training. The architecture has become fairly standardized across production deployments, even as specific implementation choices vary.

Documents are first split into chunks, commonly in the range of 512 to 1,024 tokens with some overlap between adjacent chunks, so that retrieval can return focused passages rather than entire documents. Each chunk is converted into a dense vector embedding using a model such as OpenAI’s text-embedding-3-large, Voyage AI’s embedding models, BGE-M3, or Cohere’s Embed family, which captures the chunk’s semantic meaning as a point in vector space.

Production systems typically maintain two indexes in parallel rather than relying on embeddings alone: a lexical index, commonly BM25, that matches exact terms, codes, and identifiers well, and a dense vector index that matches conceptual meaning. A technique called Reciprocal Rank Fusion combines the ranked results from both indexes into a single ranking, which in practice tends to outperform either retrieval method used alone, particularly on enterprise content that mixes structured identifiers with unstructured prose.

The initial retrieval pass typically returns more candidates than the system ultimately needs. A reranking step, using a cross-encoder model that reads the query and each candidate passage together rather than comparing precomputed vectors, reorders those candidates by relevance before the final set is passed to the language model. Only after chunking, retrieval, fusion, and reranking does the system inject the selected passages into the model’s prompt and generate a grounded answer.

This pipeline is what makes RAG dependable enough for enterprise use, and it is also what agentic AI builds directly on top of.

From RAG to Agentic RAG

Standard RAG follows a fixed, linear sequence: embed the query, retrieve, rerank, generate. It runs the same sequence regardless of how simple or complex the question is, and it retrieves exactly once.

Agentic RAG replaces that fixed sequence with a reasoning loop, in which a language model acts as an orchestrator deciding what to retrieve, from where, and whether the results are good enough to answer with.

Four capabilities distinguish agentic RAG from the standard pipeline. Query decomposition breaks a complex question into smaller sub-questions before retrieval begins, so that a question spanning multiple topics or systems can be answered by retrieving each part independently rather than forcing one retrieval pass to cover everything. Dynamic tool routing selects the appropriate retrieval method per sub-question, semantic search for conceptual questions, a lexical or SQL query for structured data and identifiers, or a web search when the answer depends on external, current information. Self-evaluation scores the relevance of retrieved context before generation; if the score falls short, the system reformulates the query and retries rather than generating an answer from weak evidence, an approach closely related to what the Self-RAG research describes as critique-guided retrieval. Multi-agent collaboration applies to the most complex tasks, where specialized sub-agents handle different domains or data sources while a coordinating agent decomposes the original query and synthesizes the sub-agents’ results into a final answer.

These patterns are not equally expensive. A simple router agent adds a few hundred milliseconds of classification overhead before sending a query to the right source. A multi-agent retrieval pattern, by contrast, can introduce five to fifteen seconds of latency and typically issues four to six language model calls where a standard RAG pipeline would issue one, increasing inference cost by a factor of roughly three to five at scale. Enterprises deploying agentic RAG in production commonly mitigate this by routing simple queries directly to standard RAG, reserving the full agentic loop for questions that genuinely require it, using smaller models for orchestration steps rather than the primary generation step, and caching decomposition results for recurring query patterns.

Where Governance Fits

An agentic search system is, functionally, an AI agent with read access to a large share of the enterprise’s knowledge, and in some deployments, write access to take action on what it finds. The identity, permission, and audit principles AppsTek has covered elsewhere in this series apply directly here. A search agent needs a defined owner, a permission boundary that mirrors the access the requesting employee already has rather than a broader service-level credential, and an audit trail connecting every retrieved passage and generated answer back to its source.

The model and infrastructure choices behind the search stack raise the same sovereignty questions covered in AppsTek’s guide to sovereign LLMs. A retrieval system that indexes an enterprise’s most sensitive internal documents, then routes queries through a language model, inherits every data residency, licensing, and jurisdictional consideration that applies to the model layer generally. Choosing where that model runs is not a separate decision from choosing how search works; it is part of the same decision.

Questions to Ask Before Deploying Agentic Search

- What is the actual retrieval quality without any agentic layer? Evaluating the retrieval foundation on its own establishes a baseline before adding orchestration complexity on top of it.

- Which queries genuinely need multi-step reasoning, versus a single retrieval pass? Routing simple queries around the agentic loop controls the latency and cost it otherwise adds.

- Does the agent respect the same access boundaries as the person asking? A search agent should inherit the requesting employee’s existing permissions rather than a broader service-level credential.

- What is the acceptable latency and cost ceiling per query? Agentic patterns can issue several times as many model calls as standard RAG; that multiplier needs a budget before rollout.

- How will retrieval failures be distinguished from reasoning failures? Evaluating retrieval and generation separately makes it possible to tell which stage produced a wrong answer.

- Where does the underlying model run, and what data sovereignty requirements apply?

Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
671296e9b6f10e940bcdee7e56ffd820
Press Eligible
Yes
Press Eligible Reason
Manuelle Prüfung nötig. Risiko: MEDIUM. Flags: ['numbers']. Stichprobe: False
Source Name
AppsTek Corp
Original Summary

<p>Table of Contents Why Enterprise Search Still Fails The Evolution of Enterprise Search How RAG Actually Works From RAG to Agentic RAG Where Governance Fits Questions to Ask Before Deploying Agentic Search  The Vendor Landscape  Building Toward Agentic Search  Summarize the article now Enterprise search has failed the same promise for three decades. Every generation [&#8230;]</p>
<p>The post <a href="https://appstekcorp.com/blog/agentic-ai-enterprise-search-rag-guide/&qu…; rel="nofollow">A Complete Guide to Agentic AI Enterprise Search</a> appeared first on <a href="https://appstekcorp.com&quot; rel="nofollow">AppsTek Corp</a>.</p>

Image URL
https://appstekcorp.com/wp-content/uploads/2026/09/Agentic-AI-in-Enterprise-Search.png
Source Node
Content Hash (SHA-256, erste 32 hex)
ae3f6dce16a592c25bcf69ee15e54805
Agentic AI Governance: A Framework for Controlling Autonomous AI
Image File
Original HTML

Table of Contents

How Agentic AI Governance Differs From Traditional AI Governance

How Sovereign AI Applies to Autonomous AI Agents

Managing AI Agent Identity and Access

Controlling AI Agent Permissions Across Enterprise Systems

Governing Model Access for AI Agents

Managing Multi-Agent AI Systems

Human Oversight for Autonomous AI Agents

Monitoring and Auditing AI Agent Activity

Building Governance Controls for Agentic AI

Managing AI Agents Across Their Lifecycle

The AI Agent Governance Lifecycle

Building a Sovereign Architecture for Agentic AI

Enterprise AI is moving beyond systems designed primarily to generate answers. Agentic AI introduces systems that can interpret goals, retrieve information, choose tools, interact with enterprise applications, coordinate with other agents, and take actions across business workflows with varying degrees of autonomy.

As those capabilities expand, enterprise control needs to expand with them. An AI assistant summarizing a document can largely be governed through controls around data, models, and user access. An autonomous agent may operate across several systems during a single task, retrieving business information, invoking APIs, selecting models, updating applications, delegating work to other agents, and triggering subsequent steps in a workflow.

Sovereign AI therefore takes on a broader meaning in an agentic environment. Control over infrastructure, data, and models remains essential, but autonomy introduces additional considerations around identity, permissions, execution authority, accountability, and oversight.

The central issue is no longer only where enterprise data resides or where an AI model runs. Enterprises also need to determine who an agent represents, which information it can access, which models and tools it can use, what actions it can perform, and how those actions can be governed and traced.

As AI agents become embedded in core business processes, maintaining control over autonomous action becomes an increasingly important part of enterprise AI sovereignty.

How Agentic AI Governance Differs From Traditional AI Governance

Traditional enterprise AI governance has largely focused on the relationship between data, models, applications, and users. Organizations establish policies around which datasets can be used, which models are approved, where information can be processed, and who can access an AI-enabled application.

Agentic AI introduces decision-making within the workflow itself. Instead of following a predefined sequence for every task, an agent can determine which information it needs, which system to query, which tool to invoke, whether another step is required, and which action should follow.

A procurement agent investigating a supplier issue could retrieve supplier information, review purchase orders, analyze delivery records, identify quality incidents, compare contractual terms, and initiate an approval workflow. Completing that task may involve several databases, enterprise applications, APIs, models, and identity systems.

Agentic AI governance therefore needs to operate across the complete workflow rather than being confined to individual applications or models. Research into sovereign AI architecture increasingly points toward multi-cloud, multi-model, and multi-agent environments where governance needs to preserve accountability, security, and resilience across interconnected systems.

Agentic AI expands governance from controlling what AI can access to controlling what AI can access, decide, and do.

How Sovereign AI Applies to Autonomous AI Agents

AI sovereignty has often been associated with infrastructure location, data residency, administrative control, and jurisdiction. Autonomous agents extend the sovereignty boundary because information and decisions can move through several environments before a business task is completed.

An agent may retrieve information from an internal enterprise application, pass selected context to an approved AI model, call another service for specialized processing, and send instructions to another agent before producing an outcome. The source data may remain within an approved environment even while portions of the workload move across different infrastructure, model, and application boundaries.

A sovereign agentic architecture needs to maintain control throughout that process. Enterprises may need policies governing:

- Where enterprise information can be processed

- Which AI models are approved for specific workloads

- Which applications an agent can access

- Which APIs and tools an agent can invoke

- What actions an agent is authorized to execute

- Which agents can communicate with one another

- When human authorization is required

- How decisions and actions are monitored

- How permissions and authority can be revoked

Not every AI agent requires the same level of control. Sovereignty requirements should reflect the sensitivity of the information involved, the business criticality of the process, applicable regulation, and the authority granted to the agent.

An internal knowledge agent working with approved corporate information carries a different risk profile from an agent processing financial transactions, patient information, government records, or critical infrastructure data. Research on sovereign AI similarly positions sovereignty as a continuum in which different workloads require different levels of localization and oversight.

Agent sovereignty is therefore defined by the information, systems, and authority involved in the workload rather than by the presence of an AI agent alone.

Managing AI Agent Identity and Access

Identity is fundamental to controlling autonomous AI inside the enterprise.

Human employees operate through defined identities that determine which applications they can access, which information they can view, and which transactions they are permitted to perform. Production AI agents require comparable identity and authorization controls.

A defined agent identity connects an autonomous system to its organizational purpose, owner, permissions, tools, and policies. Shared credentials or broadly privileged service accounts make attribution considerably more difficult, particularly when several agents interact with the same enterprise applications.

An enterprise identity model for AI agents can establish:

- Who owns and manages the agent

- Which organizational role the agent represents

- Which users or processes can invoke it

- Which applications and datasets it can access

- Which AI models it can use

- Which APIs and tools it can call

- Which business actions it can execute

- Whether it can delegate tasks to other agents

- How credentials are issued, rotated, and revoked

- How activities are attributed in audit records

Delegated authority requires equal attention. An agent acting on behalf of a finance analyst should not automatically gain access to information or transactions unavailable to that analyst. System-level agents may require additional privileges, but those privileges should remain limited to the function the agent is expected to perform.

A strong AI agent identity framework links autonomy to accountability by ensuring that every significant action can be associated with a known agent operating under defined authority.

Controlling AI Agent Permissions Across Enterprise Systems

Agentic AI derives much of its value from the ability to work across multiple systems. Broad connectivity, however, should not translate into broad authority.

Least-privilege access provides a practical foundation for governing enterprise AI agents. An agent should receive access only to the information, systems, and actions required for its approved purpose.

A procurement agent, for example, may need supplier records, purchase orders, contract information, and quality data while having no legitimate reason to access payroll or employee information. A customer service agent may require access to account history while needing additional authorization before modifying contractual terms or issuing a significant refund.

Permissions also need to distinguish between different types of agent activity.

The distinction between retrieving information and executing an action becomes increasingly important as agents gain autonomy. An agent identifying a payment exception carries a very different level of operational risk from an agent authorized to release the payment.

Granular permissions allow enterprises to automate routine activities while reserving stronger controls for actions with greater financial, regulatory, security, or operational consequences.

Governing Model Access for AI Agents

Enterprise agents are increasingly likely to operate across multiple AI models rather than relying on a single foundation model.

A general-purpose model may support reasoning, a specialized model may process documents, another may perform code analysis, and a smaller private model may handle sensitive enterprise information. Agent orchestration can also select models dynamically according to the requirements of a task.

Model access therefore becomes an important part of agentic AI governance.

Enterprise information should not be routed automatically to any model that happens to be available. Approved model selection can depend on data classification, workload sensitivity, inference location, jurisdiction, model security, provider terms, performance requirements, and regulatory obligations.

A workload containing public information may allow the agent to use a broader range of approved models. A workflow involving regulated or highly sensitive information may restrict processing to models operating within specific infrastructure or geographic boundaries.

Model governance also needs to account for change. Model versions evolve, providers modify services, deployment locations change, and new models are introduced into enterprise environments.

Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
fd0b10a9238394277a3ab3462ce3811e
Press Eligible
Yes
Press Eligible Reason
Informational article on enterprise AI agent governance and controls.
Source Name
AppsTek Corp
Original Summary

<p>Table of Contents How Agentic AI Governance Differs From Traditional AI Governance How Sovereign AI Applies to Autonomous AI Agents Managing AI Agent Identity and Access Controlling AI Agent Permissions Across Enterprise Systems Governing Model Access for AI Agents Managing Multi-Agent AI Systems Human Oversight for Autonomous AI Agents Monitoring and Auditing AI Agent Activity [&#8230;]</p>
<p>The post <a href="https://appstekcorp.com/blog/sovereign-ai-agentic-ai-governance/&quot; rel="nofollow">Agentic AI Governance: A Framework for Controlling Autonomous AI</a> appeared first on <a href="https://appstekcorp.com&quot; rel="nofollow">AppsTek Corp</a>.</p>

Image URL
https://appstekcorp.com/wp-content/uploads/2026/09/traditional-vs-agentic-AI-governance-boundary-comparison.png
Source Node
Content Hash (SHA-256, erste 32 hex)
0b7f458c89a0a189f1f9ede4fdaa1fa1
Sovereign AI Architecture: The Enterprise Stack Explained
Image File
Original HTML

Table of Contents

Sovereign AI Architecture Goes Beyond Infrastructure

Data Residency Is Only the Starting Point

The Sovereign AI Enterprise Stack

2. Data and Enterprise Knowledge

4. Applications, Integrations and AI Agents

5. Security, Governance and Observability

Sovereignty Should Follow the Workload

Architecture for Choice, Not Isolation

Building a Sovereignty Baseline

Artificial intelligence is moving deeper into enterprise operations, and the architecture supporting it is becoming increasingly distributed. A single AI workload may depend on enterprise data stored in one environment, a foundation model hosted elsewhere, a vector database containing proprietary knowledge, APIs connecting business systems, and AI agents capable of making decisions or initiating actions.

That distributed model changes the boundaries of control.

Digital sovereignty has traditionally focused on where data is stored, which jurisdiction governs it, and who controls the underlying infrastructure. Those considerations remain important, but they no longer cover the full AI lifecycle. Prompts, embeddings, retrieved context, model inference, AI-generated outputs, agent memory, application integrations, and operational logs can all move through different services and providers before an AI task is completed.

Sovereign AI architecture extends control across this entire enterprise AI stack. It brings infrastructure, data, models, applications, agents, security, and agentic AI governance into the same architectural conversation.

The objective is not to isolate every workload or build every component internally. A practical sovereign AI architecture provides enough control to determine where AI runs, how information moves, which models and providers participate, what AI systems are permitted to do, and how those decisions can be governed over time.

Sovereign AI Architecture Goes Beyond Infrastructure

Sovereign AI architecture is the design of an AI environment around defined requirements for control, jurisdiction, resilience, security, and operational autonomy.

The level of sovereignty required can vary substantially between workloads. An AI assistant working with public marketing information has a different risk profile from a system processing patient records, financial information, government data, or operational information from critical infrastructure.

Sovereignty therefore operates more effectively as a continuum than as a binary designation. Some workloads may only require local data residency and standard enterprise security controls. Others may require stronger restrictions across infrastructure, models, encryption, administrative access, and even physical isolation.

Research across nearly 2,000 organizations suggests that sovereignty measures may be necessary for only about one-third of AI initiatives, with the degree of localization varying even within those workloads.

The architecture needs to support those differences without creating a separate AI environment for every use case.

Sovereign AI is not about making every AI workload local. It is about applying the right level of control to the right workload while retaining the flexibility to change providers, models, and infrastructure as requirements evolve.

Data Residency Is Only the Starting Point

Data sovereignty and AI data residency remain foundational, particularly in regulated industries. The complexity begins once enterprise information enters an AI workflow.

A typical Retrieval-Augmented Generation application illustrates the issue. Source documents may remain within an approved region, while retrieved information is sent to an external model endpoint for inference. Embeddings may be generated through another service and stored in a separate vector database. Conversation history, monitoring information, or model logs may be retained in additional environments.

The source data can remain compliant at rest while other parts of the AI workload move outside the intended control boundary.

Generative and agentic AI also introduce new information assets that sit alongside traditional enterprise records:

- Prompts and system instructions

- Training and fine-tuning datasets

- Embeddings and vector stores

- Retrieved context

- Model inputs and outputs

- Conversation history

- Agent memory

- Evaluation data

- Operational and audit logs

Each asset can contain, reproduce, or encode sensitive enterprise information. Sovereign AI architecture must account for where these assets are processed, how long they are retained, who can access them, and whether they cross jurisdictional or organizational boundaries.

The sovereignty boundary therefore follows the information through the AI lifecycle rather than ending at the database.

The Sovereign AI Enterprise Stack

Enterprise AI sovereignty can be viewed across five connected architectural layers.

The strength of a sovereign AI stack depends less on any single layer than on how consistently control is maintained across all of them.

1. Infrastructure and Compute

Infrastructure establishes where AI workloads physically and operationally run. The available environment can include public cloud, sovereign cloud, private cloud, regional data centers, on-premises infrastructure, dedicated GPU capacity, and edge computing.

The architectural decision extends beyond cloud or on-premises deployment. It includes questions around infrastructure ownership, administrative control, jurisdiction, encryption, operational responsibility, and provider dependency.

For every critical workload, enterprises need visibility into:

- Where compute is physically located

- Who operates the infrastructure

- Who holds privileged administrative access

- Which legal jurisdiction applies

- How encryption and key ownership are managed

- Which external services remain dependencies

- Whether the workload can be moved if requirements change

Different workloads can then be placed in environments that reflect their actual sensitivity and business criticality.

A global infrastructure environment may provide the scale and innovation required for many AI workloads. Highly sensitive workloads may require local processing, dedicated infrastructure, stronger operational controls, or isolation. Sovereign AI infrastructure increasingly needs to support both ends of that spectrum.

Hybrid and multi-cloud AI architectures consequently play an important role. They allow organizations to combine global capability with stronger local control where it is required, rather than forcing every workload into a single sovereign AI infrastructure model.

2. Data and Enterprise Knowledge

AI expands the enterprise data boundary.

Traditional governance focuses heavily on databases, documents, data warehouses, and data lakes. Generative AI adds retrieval repositories, embeddings, vector stores, prompts, model outputs, and persistent memory. Agentic AI expands it further as information begins moving between AI systems, APIs, and enterprise applications.

A sovereign data architecture requires control over both the source information and the additional knowledge assets created as AI processes that information.

Access control is particularly important. Connecting an AI application to ERP, CRM, HR, finance, engineering, or operational systems should not create a new route around established permissions. Information that is restricted in a source application must remain restricted when accessed through an AI interface.

Identity-aware retrieval, encryption, retention policies, auditability, and policy enforcement therefore become fundamental parts of enterprise AI architecture.

Every additional layer extends the surface that sovereignty controls need to cover.

3. Models and Intelligence

Model sovereignty is emerging as one of the most important gaps in enterprise AI architecture.

Few enterprises are likely to standardize on a single model. Production environments increasingly combine proprietary foundation models, open models, small language models, domain-specific models, and internally fine-tuned models. The choice may change according to accuracy, privacy, cost, latency, industry context, or regulatory requirements.

A multi-model environment creates additional questions around control. Where does inference take place? How are prompts and outputs handled? Can information be retained by the model provider? How are model versions and updates managed? Can one model be replaced by another without redesigning the entire application? Can the organization trace which model generated a specific output?

Model provenance becomes particularly important when AI contributes to regulated, sensitive, or business-critical decisions. Governance needs to extend beyond approving a model for use and into understanding how that model behaves once it becomes part of a production workflow.

The gap between data sovereignty and model sovereignty is already significant. A global 2025 survey found that 60% of organizations had applied sovereignty or residency requirements to data and 46% to infrastructure. That figure dropped to 32% for applications and only 22% for AI models.

The decline higher in the stack creates a structural blind spot. Protecting enterprise data has limited value if the model processing that information operates outside the intended control framework.

4. Applications, Integrations and AI Agents

Agentic AI introduces a more consequential dimension of sovereignty because AI systems are beginning to move beyond generating information.

An AI agent can retrieve enterprise data, select a model, invoke an API, interact with another application, communicate with another agent, and initiate an action. The architecture is no longer governing only information access. It is governing execution, which is why agentic AI governance is emerging as a distinct architectural requirement rather than an extension of existing AI policy.

Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
af88c532406162bdb389f387e5dad83f
Press Eligible
Yes
Press Eligible Reason
Manuelle Prüfung nötig. Risiko: MEDIUM. Flags: ['numbers']. Stichprobe: False
Source Name
AppsTek Corp
Original Summary

<p>Table of Contents Sovereign AI Architecture Goes Beyond Infrastructure Data Residency Is Only the Starting Point The Sovereign AI Enterprise Stack 1. Infrastructure and Compute 2. Data and Enterprise Knowledge 3. Models and Intelligence 4. Applications, Integrations and AI Agents 5. Security, Governance and Observability Sovereignty Should Follow the Workload Architecture for Choice, Not Isolation [&#8230;]</p>
<p>The post <a href="https://appstekcorp.com/blog/sovereign-ai-architecture-enterprise-stack…; rel="nofollow">Sovereign AI Architecture: The Enterprise Stack Explained</a> appeared first on <a href="https://appstekcorp.com&quot; rel="nofollow">AppsTek Corp</a>.</p>

Image URL
https://appstekcorp.com/wp-content/uploads/2026/09/five-layer-sovereign-AI-enterprise-stack-diagram.png
Source Node
Content Hash (SHA-256, erste 32 hex)
7a7d55bc591475b70d8f9c2af1221f49
Sovereign LLMs: When Does an Enterprise Need One?
Image File
Original HTML

Enterprise AI conversations are narrowing to a more specific question than they were a year ago. It is no longer only whether to use a large language model, but which model, whose infrastructure it runs on, and under which jurisdiction’s laws it operates. As organizations move generative AI from pilots into regulated, revenue-bearing workflows, the model layer itself becomes a sovereignty and AI governance decision, not just a technology choice.

This is the third piece in AppsTek’s sovereign AI series. The first article mapped the full enterprise stack across data, infrastructure, sovereign cloud, applications, and models. The second examined how sovereignty extends into autonomous agents. This piece goes one layer deeper into a question enterprise architects are asking with increasing urgency: when does an organization actually need a sovereign LLM, meaning a model it can control, host, or restrict to a defined jurisdiction, rather than a general-purpose model consumed through a public API?

What Makes an LLM "Sovereign"

A sovereign LLM is not simply a model that happens to run in a particular country. Sovereignty at the model layer spans four related dimensions.

Territorial control determines where model weights, prompts, and outputs are physically processed and stored. Operational control determines who can modify, retrain, fine-tune, or take the model offline, and under what conditions. Technological control determines whether the organization owns or licenses the model weights outright, or is dependent on a provider’s roadmap and API availability. Legal control determines which jurisdiction’s courts, subpoenas, and disclosure laws, including frameworks such as the CLOUD Act, apply to the data flowing through the model.

A commercial API-based model can satisfy some of these dimensions and not others. A model hosted in-region by a hyperscaler, sometimes marketed as a sovereign cloud offering, may satisfy territorial control while remaining subject to a foreign parent company’s legal obligations. A self-hosted open-weight model can satisfy all four dimensions, at the cost of taking on the operational work a provider would otherwise handle.

Why This Question Has Become Urgent

Three forces are pushing sovereign LLM decisions onto enterprise roadmaps faster than most architecture teams expected.

Regulatory exposure is the most immediate. The EU AI Act phases in on a fixed timeline: prohibited AI practices became enforceable in February 2025, obligations for general-purpose AI model providers, including transparency and training-data documentation, took effect in August 2025, and obligations for high-risk AI systems, including conformity assessments, reach full enforcement in August 2026. An LLM used in employment screening, credit decisions, healthcare triage, or critical infrastructure can trigger high-risk classification regardless of where the model happens to run, and high-risk systems require documentation, audit trails, and conformity assessments that many general-purpose API services are not built to expose in full.

Jurisdictional risk compounds the regulatory picture. Legal frameworks such as the US CLOUD Act can compel a provider to disclose data to a foreign government regardless of where that data is physically stored, a conflict that the Schrems II ruling found structurally difficult to reconcile with EU data protection law. For enterprises operating across borders, this means storage location alone does not resolve legal exposure.

Investment and market signals confirm the shift is not theoretical. Gartner forecasts worldwide sovereign cloud infrastructure-as-a-service spending will reach approximately 80 billion dollars in 2026, a 35.6 percent increase over 2025, with governments and regulated industries such as energy, utilities, and telecommunications as the leading buyers. NVIDIA has reported that its sovereign AI revenue roughly tripled to more than 30 billion dollars in fiscal 2026. In a McKinsey survey of roughly 300 executives, investors, and government officials, 71 percent characterized sovereign AI as an existential concern or a strategic imperative rather than a secondary consideration.

None of this means every enterprise needs to self-host every model. It means the decision now deserves a deliberate framework rather than a default.

The Deployment Spectrum

Sovereignty over an LLM is not binary. In practice, enterprises choose a point along a spectrum, trading operational simplicity for control.

At one end, a public multi-tenant API offers the least control and the least operational burden. Moving along the spectrum, a data-residency or regional API keeps processing within a defined geography while the underlying infrastructure and legal entity remain the provider’s. A private or dedicated-tenancy deployment isolates compute and, in some cases, model weights within a customer-controlled environment while a vendor still manages the platform. At the far end, a fully self-hosted open-weight model, whether in a private cloud or an air-gapped on-premises environment, gives the enterprise direct control over weights, infrastructure, and data flow, along with full responsibility for operating it.

Most enterprises will not standardize on a single point on this spectrum. A workload processing public marketing content has little reason to bear the operational cost of self-hosting. A workload processing regulated health records, government data, or proprietary source code may have little choice but to move toward the self-hosted end.

The Technical Decision Criteria

Five factors determine where a given workload should sit on that spectrum.

Data classification and workload sensitivity: Public or already-disclosed information tolerates broader model access. Regulated, proprietary, or classified information narrows the acceptable set of deployment options, sometimes to a single self-hosted or air-gapped tier.

Regulatory classification: Whether a use case falls under the EU AI Act’s high-risk category, or under sector-specific rules such as financial services or healthcare regulation, determines how much documentation, auditability, and human oversight the deployment must support. These requirements are often easier to satisfy with infrastructure the enterprise directly controls, but they still depend on AI governance processes that extend well beyond the deployment choice itself.

Token volume and cost economics: Cost does not favor self-hosting by default. Based on published self-hosting cost analyses, commercial APIs typically remain the more economical choice below roughly 5 million tokens processed per day. Between 5 million and 50 million tokens per day, the answer depends heavily on sustained utilization. Above roughly 50 million tokens per day at steady load, self-hosted infrastructure tends to become the lower-cost option. These figures are illustrative rather than universal and should be validated against current provider pricing and actual workload patterns before use in a business case.

Licensing terms: Open-weight models are not uniformly open. Meta’s Llama 4 community license, for example, excludes companies domiciled in the European Union from using its multimodal capabilities, a restriction enterprises must check against their own entity structure before standardizing on a given model family. License review belongs in the same governance process as data classification, not as an afterthought.

Operational readiness: Self-hosting shifts cost from a per-token fee to fixed infrastructure plus engineering time. Industry guidance on self-hosted LLM operations suggests budgeting a minimum of half to a full full-time engineering role in the first year for model serving, monitoring, and governance work, a cost that frequently exceeds the hardware budget itself for mid-sized deployments.

Infrastructure Requirements for Self-Hosting

Enterprises that conclude a workload belongs on the self-hosted end of the spectrum face a second, more technical set of decisions: how much compute the model actually requires.

Memory, specifically GPU VRAM, is typically the binding constraint rather than raw compute throughput. A useful approximation is that total VRAM required equals model weights plus key-value cache plus operational overhead, with a safety margin of roughly 20 to 30 percent added to the base figure. A 70-billion-parameter model quantized to INT4 precision requires approximately 39 gigabytes for weights alone, which can fit on a single high-end workstation GPU; the same model at full FP16 precision requires roughly 140 gigabytes, which typically requires multiple data center-class GPUs.

Quantization is the primary lever enterprises use to fit larger models into smaller infrastructure footprints. Reducing a model from FP16 to INT8 or INT4 precision cuts memory requirements substantially, generally at a measurable but often acceptable cost to output quality, and evaluating that quality tradeoff against the specific workload is a necessary step before committing to a hardware tier.

Beyond raw hardware, production self-hosting requires an inference serving layer. Options in common enterprise use include vLLM, a widely adopted default that reduces memory fragmentation; SGLang, which some benchmarks show delivering meaningfully higher throughput on certain model architectures; TensorRT-LLM, tuned specifically for NVIDIA hardware; and Text Generation Inference, which integrates closely with the Hugging Face ecosystem. Lighter tools such as Ollama and llama.cpp are common for proof-of-concept work but are generally not the production standard at enterprise scale.

Self-hosting also removes the content filtering, abuse prevention, and safety tooling that commercial API providers typically bundle into their service.

Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
e05b0c9962170d75f297c0b23247bc80
Press Eligible
Yes
Press Eligible Reason
Manuelle Prüfung nötig. Risiko: MEDIUM. Flags: ['finance', 'legal', 'numbers']. Stichprobe: False
Source Name
AppsTek Corp
Original Summary

<p>Summarize the article now Enterprise AI conversations are narrowing to a more specific question than they were a year ago. It is no longer only whether to use a large language model, but which model, whose infrastructure it runs on, and under which jurisdiction&#8217;s laws it operates. As organizations move generative AI from pilots into regulated, revenue-bearing workflows, the [&#8230;]</p>
<p>The post <a href="https://appstekcorp.com/blog/sovereign-llm-enterprise-deployment-guide/…; rel="nofollow">Sovereign LLMs: When Does an Enterprise Need One? </a> appeared first on <a href="https://appstekcorp.com&quot; rel="nofollow">AppsTek Corp</a>.</p>

Image URL
https://appstekcorp.com/wp-content/uploads/2026/09/Sovereign-LLMs-img.png
Source Node
Content Hash (SHA-256, erste 32 hex)
25c6bc128f0ef4a9b15a60e824caa182