Pulse & Canadian Ringette
Image File
Original HTML

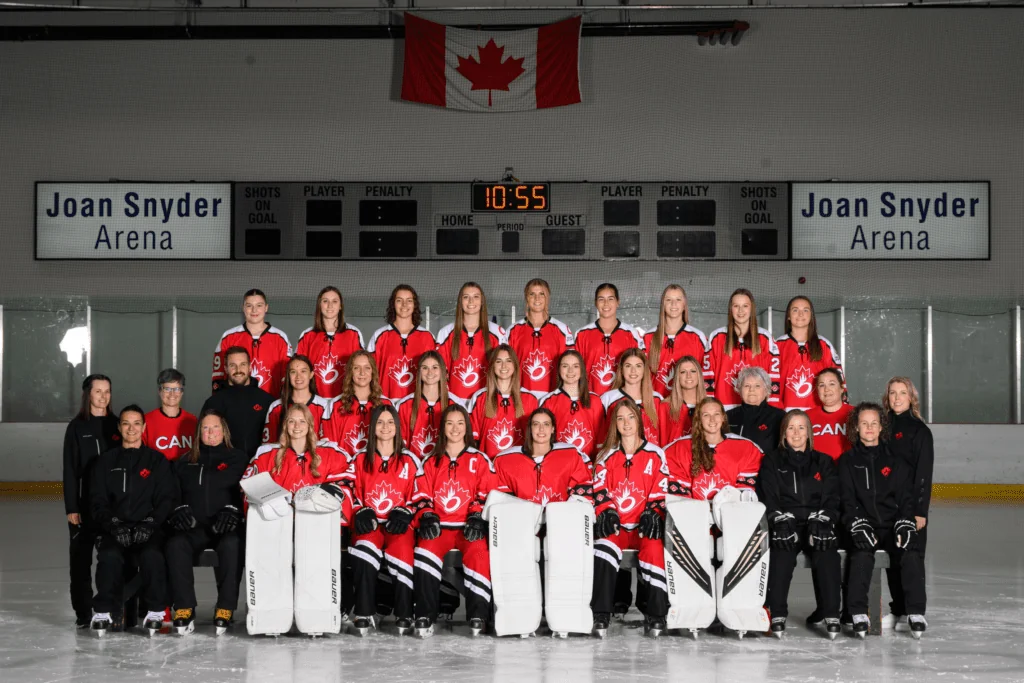
Pulse was proud to support Team Canada again this year in the 2023 World Ringette Championships held here in Calgary, Alberta, from October 29 to November 4, 2023. Our contribution to Ringette Canada went directly to help cover the athletes’ costs, as many of them travelled to Calgary from other provinces throughout Canada.

We at Pulse were excited to cheer on the young athletes representing our country, including Calgary U21 team member 19-year-old Regan Meier and a group of employees who attended an exciting Canada versus Finland game.

The 2023 World Ringette Championships were a celebration of the 60th Anniversary of Ringette showcasing the fastest game on ice.

Class (B2B/B2C)
Ignore
Ingest Status
Rejected
Dedupe hash
4f21c5b7d8134ee77c1e9e7daf508a3d
Press Eligible
No
Press Eligible Reason
Text too short (110 words. Min: 150)
Source Name
Pulse Seismic Inc.
Original Summary

<p><img alt="" class="attachment-post-thumbnail size-post-thumbnail wp-post-image" height="67" src="https://pulseseismic.com/wp-content/uploads/2023/11/Hockey-Canada-100x6…; width="100" /></p>Pulse was proud to support Team Canada again this year in the 2023 World Ringette Championships held here in Calgary, Alberta, from October 29 to November 4, 2023. Our contribution to Ringette Canada went directly to help cover the athletes&#8217; costs, as many of them travelled to Calgary from other provinces throughout Canada. We at Pulse were excited to cheer ... <div><a class="more-link" href="https://pulseseismic.com/2023/11/29/pulse-canadian-ringette-2/">Read More</a></div>

Image URL
https://pulseseismic.com/wp-content/uploads/2023/11/Hockey-Canada-1024x683.png
Source Node
Content Hash (SHA-256, erste 32 hex)
43e9c7c3775abe3d71b05bed5fd6c28f
Ronald McDonald House Charities
Image File
Original HTML

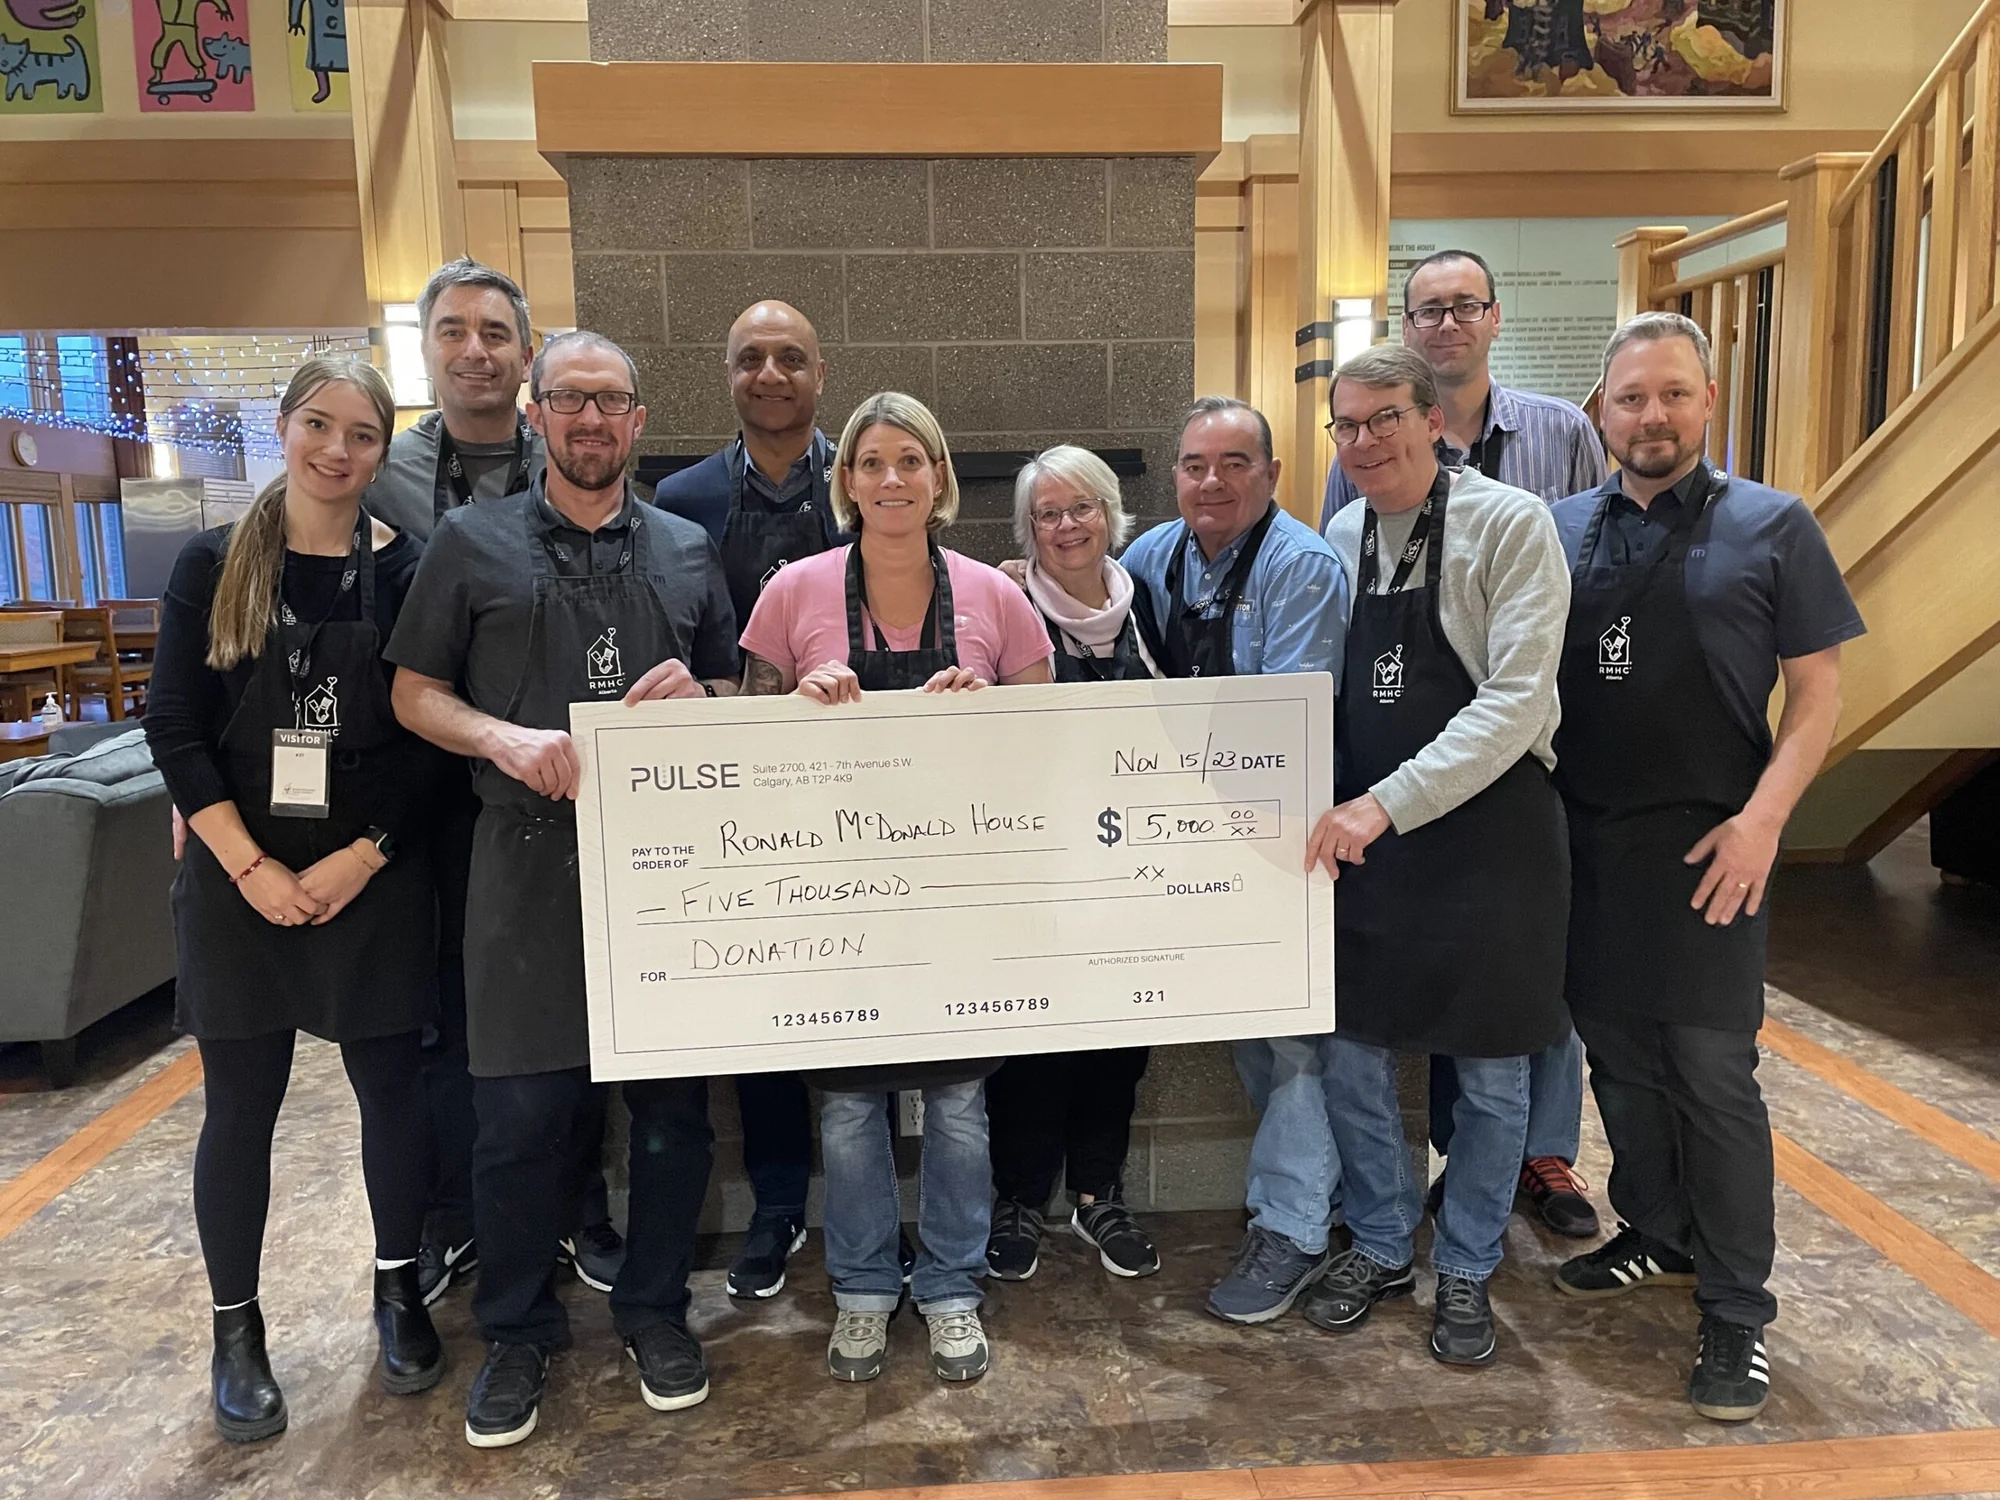
“Our people are at the core of our success, and our team has shown leadership and commitment to supporting our clients, industries, and partnerships through strong corporate citizenship, supporting causes in the communities where we live and work.” – Neal Coleman, President & CEO, Pulse

At Pulse, we believe strong communities make strong teams and every year Pulse strives to support community wide causes.

In 2021, Pulse supported several community organizations financially, including the Calgary Food Bank, Canadian Cancer Society, Canadian Mental Health Association, Discovery House Family Violence Prevention Society, Distress Centre, Inn from The Cold Society, Urban Society for Aboriginal Youth, and YouthLink Calgary – Calgary Police Interpretive Centre.

Our committed team members also volunteer their time to support many community causes

and initiatives they are passionate about.

Echoing Our Sustainability Commitment, we want to show our work and commitment to building a sustainable future for our industry and to all those with whom we work.

“Sustainability is embedded throughout our corporate strategy, recognizing the link between environmental, social and governance (ESG) initiatives and value creation are aligned with our goals and priorities.” – Pamela Wicks, VP Finance and Chief Financial Officer.

Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
13fd44e637def7f698b984269ae2126c
Press Eligible
Yes
Press Eligible Reason
Corporate community initiatives and ESG commitment from Pulse.
Source Name
Pulse Seismic Inc.
Original Summary

<p><img alt="" class="attachment-post-thumbnail size-post-thumbnail wp-post-image" height="75" src="https://pulseseismic.com/wp-content/uploads/2023/12/Ronald-McDonald-Hou…; width="100" /></p>“Our people are at the core of our success, and our team has shown leadership and commitment to supporting our clients, industries, and partnerships through strong corporate citizenship, supporting causes in the communities where we live and work.” – Neal Coleman, President &#38; CEO, Pulse At Pulse, we believe strong communities make strong teams and every year Pulse strives to ... <div><a class="more-link" href="https://pulseseismic.com/2023/12/13/ronald-mcdonald-house-charities/">R… More</a></div>

Image URL
https://pulseseismic.com/wp-content/uploads/2023/12/Ronald-McDonald-House-2-scaled.jpg
Source Node
Content Hash (SHA-256, erste 32 hex)
eaa68bc2870440b540ba2af24e77a389
Commitment to Sustainability
Image File
Original HTML

June 7, 2023 — As part of Pulse’s commitment to sustainability, we have partnered with the Ann & Sandy Cross Conservation Area in their reforestation project and supported their educational programming. In 2023, the first year of our three-year partnership, we held our initial Pulse team tree-planting day to assist in the restoration of forests and ecosystems. The original idea behind this partnership was to plant trees to help offset the energy used in Pulse’s office space.

Class (B2B/B2C)
Ignore
Ingest Status
Rejected
Dedupe hash
14a3065ca5906e5cd9af89ad8398230c
Press Eligible
No
Press Eligible Reason
Text too short (79 words. Min: 150)
Source Name
Pulse Seismic Inc.
Original Summary

<p><img alt="" class="attachment-post-thumbnail size-post-thumbnail wp-post-image" height="75" src="https://pulseseismic.com/wp-content/uploads/2024/03/Ann-Sandy-Cross-100…; width="100" /></p>June 7, 2023 &#8212; As part of Pulse’s commitment to sustainability, we have partnered with the Ann &#38; Sandy Cross Conservation Area in their reforestation project and supported their educational programming. In 2023, the first year of our three-year partnership, we held our initial Pulse team tree-planting day to assist in the restoration of forests and ecosystems. The original idea ... <div><a class="more-link" href="https://pulseseismic.com/2024/03/21/commitment-to-sustainability/">Read More</a></div>

Image URL
https://pulseseismic.com/wp-content/uploads/2024/03/Ann-Sandy-Cross.png
Source Node
Content Hash (SHA-256, erste 32 hex)
79ae3e0e4302dadf66d30d63347b86ff
Pulse 2024 Tree Planting Event
Image File
Original HTML

On June 13, 2024 the Pulse employees returned to the Ann and Sandy Cross Conservation Area (ASCCA) for our 2nd annual tree planting day. In 2023 we entered into a three year partnership with ASCCA to support their ongoing rewilding and education initiatives. After the Pulse team spent a day planting tree species native to the area, the Midnapore 75th Boy Scouts troupe volunteered their time to plant the remainder of the trees purchased for 2024. The ASCCA hosts thousands of students every year, including many youth who are new to Canada. We are very proud to support their environmental education in nature.

Class (B2B/B2C)
Ignore
Ingest Status
Rejected
Dedupe hash
d8238c56292259c7608167978a8bfdfd
Press Eligible
No
Press Eligible Reason
Text too short (103 words. Min: 150)
Source Name
Pulse Seismic Inc.
Original Summary

<p><img alt="" class="attachment-post-thumbnail size-post-thumbnail wp-post-image" height="77" src="https://pulseseismic.com/wp-content/uploads/2024/11/Tree-Planting-2-100…; width="100" /></p>On June 13, 2024 the Pulse employees returned to the Ann and Sandy Cross Conservation Area (ASCCA) for our 2nd&#160;annual tree planting day. In 2023 we entered into a three year partnership with ASCCA to support their ongoing rewilding and education initiatives. After the Pulse team spent a day planting tree species native to the area, the Midnapore 75th&#160;Boy Scouts ... <div><a class="more-link" href="https://pulseseismic.com/2024/11/07/pulse-2024-tree-planting-event/">Re… More</a></div>

Image URL
https://pulseseismic.com/wp-content/uploads/2024/11/Tree-Planting-2.jpg
Source Node
Content Hash (SHA-256, erste 32 hex)
c538495b7a6b6b76336968e847d2bf0a
2024 Alberta Special Olympics
Image File
Original HTML

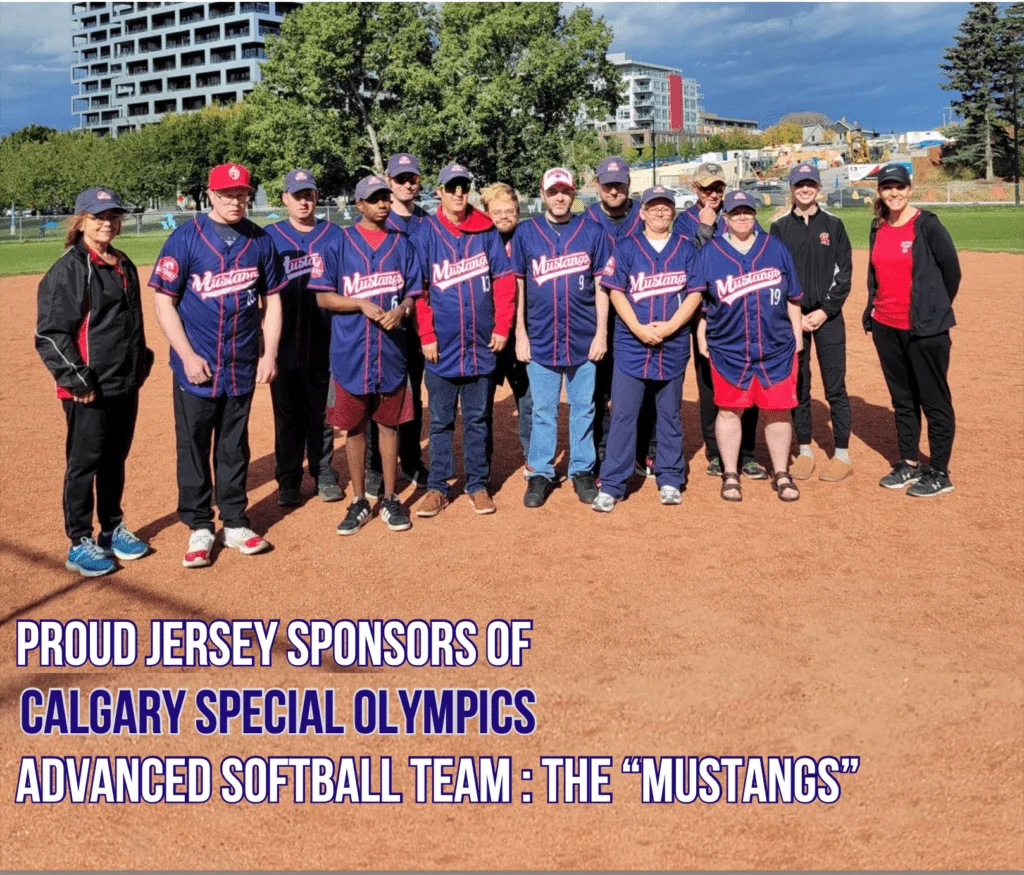
In the summer of 2024, Pulse sponsored The Mustangs, an Advanced Special Olympics Softball Team in Calgary coached by one of our employees. With Pulse’s help, the team received new uniforms which they wore proudly to compete. We are happy to be included in the supporters of Special Olympics Alberta, assisting in the provision of programs, mentorship and resources required by the athletes, coaches and volunteers to change the lives of thousands of individuals with an intellectual disability across Alberta.

Class (B2B/B2C)
Ignore
Ingest Status
Rejected
Dedupe hash
63750e074e1e72da2294568c124493c4
Press Eligible
No
Press Eligible Reason
Text too short (81 words. Min: 150)
Source Name
Pulse Seismic Inc.
Original Summary

<p><img alt="" class="attachment-post-thumbnail size-post-thumbnail wp-post-image" height="85" src="https://pulseseismic.com/wp-content/uploads/2024/11/Special-Olympics-Sp…; width="100" /></p>In the summer of 2024, Pulse sponsored  The Mustangs, an Advanced Special Olympics Softball Team in Calgary coached by one of our employees. With Pulse’s help, the team received new uniforms which they wore proudly to compete. We are happy to be included in the supporters of  Special Olympics Alberta, assisting in the provision of programs, mentorship and resources required ... <div><a class="more-link" href="https://pulseseismic.com/2024/11/07/2024-alberta-special-olympics/">Read More</a></div>

Image URL
https://pulseseismic.com/wp-content/uploads/2024/11/Special-Olympics-Sponsorship-1024x875.png
Source Node
Content Hash (SHA-256, erste 32 hex)
8148ced863e3af00ce8b1a8f634c8b0a
Together, we care for kids.
Image File
Original HTML

On March 24, 2026, Pulse employees volunteered their time with an incredible organization supporting Calgary’s school communities — Brown Bagging for Calgary Kids (BB4CK).

The BB4CK community works to improve food security for children and families across Calgary, currently supporting 290+ schools. With 2 in 5 children in Alberta experiencing food insecurity, thousands of kids right here in Calgary rely on school lunches for the energy they need to learn, grow, and thrive.

For over 35 years, BB4CK has connected community support to children who need it most and now reaches around 8,000 students every school day. We’re proud to be part of this important work, grateful for the opportunity to give back, and look forward to continuing our support in the years ahead.

Class (B2B/B2C)
Ignore
Ingest Status
Rejected
Dedupe hash
49d9df6c20e50ae4b0abab64bf1e029c
Press Eligible
No
Press Eligible Reason
Text too short (126 words. Min: 150)
Source Name
Pulse Seismic Inc.
Original Summary

<p><img alt="" class="attachment-post-thumbnail size-post-thumbnail wp-post-image" height="178" src="https://pulseseismic.com/wp-content/uploads/2026/03/PXL_20260324_195903…; width="100" /></p>On March 24, 2026, Pulse employees volunteered their time with an incredible organization supporting Calgary’s school communities — Brown Bagging for Calgary Kids (BB4CK). The BB4CK community works to improve food security for children and families across Calgary, currently supporting 290+ schools. With 2 in 5 children in Alberta experiencing food insecurity, thousands of kids right here in Calgary rely ... <div><a class="more-link" href="https://pulseseismic.com/2026/03/31/together-we-care-for-kids/">Read More</a></div>

Image URL
https://pulseseismic.com/wp-content/uploads/2026/03/PXL_20260324_195903174.MP-X2.jpg
Source Node
Content Hash (SHA-256, erste 32 hex)
52eb3a13ecae111d957e3072258de084
Snowflake Decision Fast: Low-Latency AI Decision Models
Image File
Original HTML

Just two weeks ago, we introduced Snowflake Decision in Cortex AI Functions in private preview. Built specifically for classification, scoring, filtering and routing, it tackles high-volume tasks with bounded answers. Instead of open-ended text, it returns a typed answer, such as a specific category, a numerical score or a yes/no probability, that your workflow can act on directly.

Our customers quickly highlighted the need for “arcade speed” for decisions sitting inside interactive or latency-sensitive workflows, such as live routing steps, real-time fraud checks or an agent's first triage hop. In these environments, speed is critical.

Today, in private preview, we are expanding the Snowflake Decision offerings to address these needs with the following capabilities, all backed by the same governance, access controls and audit policies you already rely on:

- snowflake-decision-fast: A lower-latency variant of snowflake-decision built for workloads where response time matters just as much as decision quality.

- REST API support: Call Snowflake Decision models through Cortex AI Gateway, allowing applications, services and agents outside of SQL to use structured decision-making.

- Cortex AI Functions: snowflake-decision-fast is natively available through AI_COMPLETE in SQL.

Seeing decisions in motion: Real-time text classification

To demonstrate the interactive power of snowflake-decision-fast, we built a real-time text classification application. As a customer types a support ticket, such as a complaint about being charged twice, the application quickly evaluates the live text to make three simultaneous decisions: routing the ticket to the right team, flagging urgency and reading the customer's sentiment.

On every keystroke, the interactive application evaluates the current text state and asks the model bounded questions to determine the next workflow step. This interactive capability can be executed externally via the Cortex AI Gateway:

import os

from typesafe_sdk import Choice, Noul, Score, TypeSafeClient

client = TypeSafeClient(

api_key=os.environ["SNOWFLAKE_PAT"],

base_url="https:///api/v2/aigateways/",

model="snowflake-decision-fast",

)

response = client.system_one(

state=(

"hi i have a question about my account. i was charged twice for my "

"subscription and would like a refund. i need this resolved today "

"before our finance 5pm cutoff. this is the 3rd time i contacted support."

),

questions={

"needs_attention_now": Noul(

instructions="Does this ticket need attention now because it is urgent or time-sensitive?"

),

"team": Choice(

instructions="Which support team should handle this ticket?",

criteria={

"billing": "Payments, invoices, subscriptions, duplicate charges, refunds.",

"technical_support": "Product bugs, outages, broken integrations, API issues.",

"account_access": "Login, password, MFA, locked account, authentication.",

"sales": "Pricing, plan upgrades, renewals, contracts, purchasing.",

"general": "Unclear, mixed, or uncategorized requests.",

},

),

"customer_tone": Score(

instructions="How frustrated does the customer sound? This is about tone, not issue severity.",

criteria=["Calm", "Frustrated", "Very frustrated"],

),

},

)

print(response.nouls["needs_attention_now"].noul)

print(response.choices["team"].choice)

print(response.choices["team"].probabilities)

print(response.scores["customer_tone"].score) # 0=Calm, 1=Frustrated, 2=Very frustrated

Here it is in action:

Figure 1: With our text classification tool, you can create a support ticket, and snowflake-decision-fast makes three decisions at once, in real time: who should handle it, how urgent it is, and how the customer feels.

This interactive use case highlights the core mechanics of decision models:

- Construction bounds: The app offers only valid moves as choice options. The model cannot return an invalid action, removing the need for parsers, retry loops or complex error handling in your code.

- Probabilities as the product: The model returns the chosen value and per-option probabilities rather than free-text reasoning. A highly confident 0.99 for a "Billing" route provides a definitive signal you can threshold on for live workflows.

- Visible latency: The live interface relies on near-instant decisions as the user types, with endpoint round trips consistently completing in under 300 ms. Running on snowflake-decision-fast ensures that the latency remains low enough to provide a seamless, real-time user experience.

Scaling to massive table operations

While the REST API is ideal for single-shot, interactive decisions, the same structured decision-making capabilities are also available through Cortex AI Functions, enabling developers to apply classification and routing logic directly to large data sets using simple SQL.

Consider a global support platform that needs to triage and route millions of incoming tickets or messages every day. Using a general-purpose LLM for a narrowly defined classification task can introduce unnecessary complexity, cost and processing overhead, particularly when each record requires only a small set of structured decisions.

By using snowflake-decision-fast in AI_COMPLETE, teams can apply the same decision logic across entire tables without building separate inference pipelines or managing external API integrations.

For example, the following query classifies incoming support tickets by routing queue and determines whether each ticket requires escalation, returning structured outputs ready for downstream processing:

SELECT

ticket_id,

AI_COMPLETE(

model => 'snowflake-decision-fast',

prompt => TO_JSON({

'state': ticket_body,

'questions': {

'routing_queue': {

'type': 'choice',

'instructions': 'Determine the correct support queue for this ticket.',

'criteria': {

'billing': 'Invoices, payments, or subscription changes',

'technical': 'System errors, bugs, or API issues',

'account': 'Password resets or profile updates'

}

},

'requires_escalation': {

'type': 'noul',

'instructions': 'The customer is expressing extreme frustration or threatening to churn'

}

}

})

)::VARIANT AS decision_output

FROM incoming_support_tickets_10m;

What works for a real-time REST API call scales to high-volume classification, offline scoring and asynchronous triage directly within your data pipelines.

Speed at quality you can trust

The landscape of structured AI decision-making is evolving rapidly, and we are iterating quickly to improve both the quality and the raw execution speed of our models. Our engineering focus is to aggressively push the frontier of decision accuracy on established benchmarks while simultaneously driving down latency and compute costs for real-time applications.

snowflake-decision-fast is our latest step in giving developers the exact performance profile their architecture demands, and you can expect rapid, ongoing updates to model quality in the coming months.

Figure 2: The average accuracy and time to process table rows. The difference between snowflake-decision and snowflake-decision-fast is calculated using our internal decision benchmark.

Getting started

To request early access to the decision models, reach out to your Snowflake account team. A representative will follow up with next steps, including comprehensive private preview documentation.

Fast, structured decisions open up patterns that weren't practical before: agents that check each step before acting, pipelines that score every record as it lands and live workflows that route in real time. The question shifts from "Can we afford to put AI here?" to "Where else could a decision go?"
Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
5eee3d9d454bc6d59cd7cd6aa919adc2
Press Eligible
Yes
Press Eligible Reason
Manuelle Prüfung nötig. Risiko: MEDIUM. Flags: ['numbers']. Stichprobe: False
Source Name
Snowflake Newsroom
Original Summary

Snowflake Decision Fast brings low-latency AI decision models to Cortex AI. Classify, score and route data in real time with SQL or the REST API.

Image URL
https://www.snowflake.com/content/dam/snowflake-site/blog/general-stock-images/44-general.jpg
Source Node
Content Hash (SHA-256, erste 32 hex)
718df58b5daf5693e9aca31d85ae6c23
How to Build a Modern Fraud Detection Platform with Online ML | Snowflake
Image File
Original HTML

Fraud is a growing problem that continues to drive compliance expenses higher year after year. Achieving regulatory compliance with effective, real-time fraud prevention has quickly become one of the financial services industry's most critical and expensive challenges. Enterprise-ready fraud detection relies on robust machine learning infrastructure that continuously and dynamically analyzes transaction patterns, flags anomalies and adapts to emerging threats in real time.

Catching bad actors before a transaction clears requires production-grade infrastructure designed to detect fraud in milliseconds. In this blog post, we'll dive into how Snowflake ML addresses these real-time challenges by unifying streaming features, low-latency model serving and MLOps on a single data and ML platform. In particular, we highlight the advantages of using Snowflake’s Online Feature Store (now generally available) to productionize fraud detection workflows by serving features in less than 10ms and enabling subsecond feature freshness from real time streaming events.

Why it's hard: The real challenges

For all financial institutions, there are three core challenges that make the fraud detection problem difficult to address at enterprise scale: latency of results for real-time transactions, the ever-changing landscape of fraud tactics, and the comprehensive security and governance requirements of sensitive customer and financial data.

Addressing the latency problem

Most institutions struggle to detect fraud in real time because legacy batch pipelines and static rules engines cannot evaluate live transactions against fresh behavioral data within millisecond SLAs. Stopping fraud requires an architecture capable of delivering subsecond feature freshness. This includes using stream feature views to continuously ingest live events (e.g. logins, transactions) into a low-latency serving layer. During inference time, real-time feature views need to dynamically compute request-level metrics (e.g. comparing current transaction spend to a customer's historical baseline).

Monitoring model performance over time

Fraud models degrade as adversaries adapt. What detected synthetic identity fraud last quarter may miss the next generation of attacks this quarter. This is model drift — and most institutions discover it too late. Enterprises that are successful at monitoring performance over time have fully managed ML systems that are easy to develop, iterate and promote relevant features and models to production to seamlessly adapt to changes in the business.

Keeping all data secure and governed

For most legacy fraud detection systems, inference calls often send data to an external platform. Egress leads to governance risk level that may be unacceptable for regulated financial institutions. End-to-end data lineage and data governance are must-haves for a production fraud detection system that includes sensitive data.

These business challenges stem directly from traditional ML infrastructure limitations — and solving them requires an end-to-end, real-time ML platform built for enterprise scale.

What successful fraud detection looks like

VALID Systems helps financial institutions prevent fraud in real time across teller, ATM and mobile channels, guaranteeing over $6 billion in immediately available funds each month across more than 425 million unique accounts.

After its legacy solution had reached its ceiling, VALID Systems rearchitected its fraud detection ML platform on Snowflake so that all features, training data, models and inference exist in one place, maintaining the same API contract with zero egress.

VALID’s models now optimize for the dollar value of the decisions they make, not just whether they got a row right or wrong. This shift in objective compounds performance. A small improvement targeting the highest-risk transactions outweighs a larger improvement spread evenly across all of them. Every tuning run is logged and fully auditable, so compliance teams get the documentation as a byproduct of the process instead of as an afterthought.

As a result of this new platform change, VALID achieved a 7%-10% drop in deposit loss rates and detected 15%-17% more bank fraud losses.

Real-time ML at banking scale is a solved problem on Snowflake.

Michael Ring

Another customer that has modernized fraud detection at scale is Neon, which is one of Brazil's fastest-growing digital financial institutions serving over 27 million customers with payments and credit products. Every login, card payment, transfer and loan request first passes through Viper, Neon's in-house fraud engine. Viper needs fresh behavioral features, such as transaction counts over windows from minutes to months, to make a decision in real time.

Neon's previous feature store vendor Tecton was being discontinued, which gave the team a hard deadline. Neon evaluated several providers and picked Snowflake for four reasons: low latency, fresh streaming and real-time features, the same governance across online and offline features, a Pythonic developer experience, and more control with costs visible in one place.

In three months, the team rebuilt almost 300 features across eight fraud workflows on Snowflake Feature Store. As a result, Neon cut P99 feature latency from 140 ms to 72 ms, making it almost two times faster in Snowflake. Viper's service availability rose from 99.7% to 99.9% increasing the Viper’s anti-fraud coverage.

Machine learning models are at the center of our growth strategy, and that is only possible with a feature store that can grow at scale. With Snowflake Feature Store, our P99 latency dropped from around 140 milliseconds to around 72 milliseconds — almost two times faster — and our fraud engine's availability went from 99.7% to 99.9%.

Thiago Bianchi, Ph.D.

The technical blueprint for modern fraud detection

With Snowflake ML, customers such as VALID Systems and Neon are able to build robust fraud detection platforms that scale to the modern business demands because we provide the following benefits out of the box:

- Low-latency predictions: Features served in under 10 ms with the Online Feature Store and models in under 100 ms from Snowflake Model Registry.

- Integrated monitoring: The capacity to easily monitor, explain and receive alerts on performance and accuracy over time with built-in MLOps.

- Security and governance: Unified data, features and models on a single platform, eliminating risks from egress of sensitive customer data.

Online ML capabilities, including online feature serving and model serving, are at the core of real-time fraud detection workflows. Today, we are thrilled to share that Snowflake’s Online Feature Store is now generally available, joining model serving for any production use case. Built on Snowflake Postgres, our Online Feature Store serves fresh, latency-sensitive ML signals — risk scores, activity patterns and behavioral features — to models at prediction time. These workloads require thousands of predictions per second, each needing features returned in milliseconds. The Online Feature Store is integrated directly with online model serving to easily generate low-latency fraud predictions.

Once the features are computed, the model is ready to be served in real time. For model serving, Snowflake deploys trained models as fully managed inference services on Snowpark Container Services (SPCS). Any model registered in the Snowflake Model Registry can be deployed with a single API call to a dedicated REST endpoint. The model service integrates directly with the Online Feature Store, and the service automatically fetches the latest features from the online store. This tight coupling between feature retrieval and model execution means a comprehensive fraud scoring decision — from feature lookup to prediction — happens in a single network round trip, minimizing network latency and external data movement.

Figure 1: The Online Feature Store is directly integrated with online model serving, allowing customers to look up features directly from model inference requests.

Together, the Online Feature Store and online model serving, paired with our integrated ML platform, deliver the technical foundation needed to solve the industry’s biggest fraud detection hurdles. Let’s dive into how Snowflake ML addresses the most business-critical needs for financial institutions.

From event to decision in milliseconds

Catching fraud means the model must see the freshest possible signals — not features computed in last night's batch run but signals that reflect what happened seconds ago. Snowflake's online ML platform is built around streaming features that keep fraud decisions based on fresh signals as events unfold.

At the core are stream feature views, which ingest events such as transactions, logins and device signals in real time through a REST ingestion API and serve updated features with end-to-end freshness in under 200ms p50. Behind the scenes, events are written synchronously to a managed Postgres serving layer for low-latency reads. As events arrive, the Online Feature Store continuously computes time-windowed aggregations such as "total spend in the last 48 hours" or "number of transactions in the last hour," maintaining running totals rather than periodically rescanning raw event history. This means the fraud model always sees behavioral signals that reflect the very latest activity, not a stale snapshot.

For features that depend on the current request, such as the transaction amount or device fingerprint, real-time feature views compute derived values on the fly at query time. A Python function runs at inference time, combining per-request inputs with precomputed features from upstream feature views before they reach the model. For example, a fraud model can compare the current transaction amount (at request time) to a customer's rolling average spend (continuously maintained by the stream feature view) to flag anomalies the moment they occur.

Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
da42617292643af22ba6c1fdab2e8f5e
Press Eligible
Yes
Press Eligible Reason
Manuelle Prüfung nötig. Risiko: MEDIUM. Flags: ['finance', 'numbers']. Stichprobe: False
Source Name
Snowflake Newsroom
Original Summary

Learn how Snowflake ML powers real-time fraud detection with the Online Feature Store (now GA), low-latency model serving and integrated MLOps — all on a single, secure platform. See how VALID Systems cut deposit losses 7–10% with Snowflake.

Image URL
https://www.snowflake.com/content/dam/snowflake-site/blog/finserv/04-finserv.jpg
Source Node
Content Hash (SHA-256, erste 32 hex)
e733d4ce56e0a7be123d767981b1b360
Horizon Context: Put Business Knowledge to Work for AI
Image File
Original HTML

A business leader asks an AI agent: Why did customer retention decline this quarter? Before it can deliver a useful answer, the agent needs to know how your business defines retention, which customer data to use and how that data connects to the reports your teams rely on. A fluent explanation is not enough if it starts from the wrong definition or data set.

Much of that knowledge already exists in your organization. It lives in business reports, transformation logic, data documentation and the experience of your teams. When it stays scattered, every new AI use case requires people to assemble it again. That means more preparation for developers, more validation for analysts and a longer path from a business question to a decision.

At Snowflake Summit, we introduced Horizon Context: a governed context layer within Horizon Catalog that collects metadata, enriches it with business meaning and makes it useful to people, BI tools and AI agents.

Metadata connectors for 18 sources, targeted permissions for stewards to curate descriptions and automatic propagation of descriptions to supported downstream columns are now in public preview. Together with the recently redesigned Horizon Catalog Explorer, these capabilities help teams discover, enrich and reuse existing data knowledge for AI and analytics.

With Horizon Context, teams can:

- Understand data before using it with a consistent catalog experience that brings definitions, tags and contacts to the forefront.

- Reuse existing data knowledge from reports, databases and pipelines rather than reconstructing it for each AI use case.

- Troubleshoot issues and assess change impact using connected lineage across supported sources, transformations and BI tools.

- Bring business experts into context curation without granting broader control over the underlying data.

- Reduce documentation maintenance by propagating descriptions to supported downstream columns.

- Ground AI and analytics in shared context, reducing the need to recreate knowledge in each application or prompt.

Scale business understanding alongside AI adoption

In our customer conversations, enthusiasm for AI comes with practical expectations: help people find the right data, make its meaning clear and reduce dependence on a small group of experts. Teams value seeing the source behind a report and reusing documentation rather than maintaining it repeatedly. Those needs matter even more when people delegate data work to agents.

As AI adoption grows, maintaining a separate set of instructions and definitions for each agent creates more work and more opportunities for inconsistency. A shared, governed context layer gives teams a foundation they can reuse across use cases, instead of treating business understanding as a new integration project every time.

Horizon Context connects three parts of that foundation: the evidence in your data systems, the knowledge of your business experts and the tools that use both. The goal is less time reconstructing context and more time applying it to business decisions.

Build on the knowledge in your existing data investments

Your organization has already invested in the reports and data pipelines that run the business. Their metadata captures valuable evidence about how data is structured, transformed and used. Making that evidence available gives AI developers a stronger starting point than isolated table names and column lists.

Horizon Catalog's metadata connectors now support 18 sources across databases, BI and data pipeline tools. These include Power BI, Tableau, Looker, Sigma, Hex, dbt, SQL Server, Oracle, PostgreSQL, Databricks and BigQuery.

Depending on the connector and its configuration, Horizon Context collects schemas, query logs, dashboard definitions and usage signals. Teams can browse external assets alongside Snowflake objects, search their metadata and explore cross-platform lineage from the catalog.

Put data understanding front and center

The redesigned Horizon Catalog delivers a consistent experience that puts data definitions, tags and contacts front and center. Business analysts can easily find data assets and understand what they mean, how they can be used and whom to ask for clarification. Together with metadata connectors, this makes Horizon Catalog a single pane of glass for understanding data across Snowflake and connected systems, helping teams and agents discover the right data and use it with shared business context.

When a retention report shows an unexpected decline, teams need to investigate whether it reflects a business change or a data issue. Across supported, connected systems, lineage helps them trace the report through transformations to its source data and identify where to investigate. Before changing an upstream table or column, they can follow the same dependencies downstream to assess which reports could be affected.

Snowflake CoCo brings this context into an AI-assisted workflow. Teams can ask questions such as "Where does this retention data set come from?" or "Which downstream reports depend on this column?" CoCo can use available lineage to help investigate issues and assess change impact, reducing the need to reconstruct dependencies manually.

These connectors collect metadata; they do not require replicating the underlying data sets into Snowflake. They make existing data knowledge easier to discover and reuse, while governed business definitions provide the additional meaning needed to interpret it.

Bring business expertise into your AI foundation

The people who understand customer retention may not be the people who manage the database. Yet their knowledge of customer status, exclusions and reporting conventions is essential to interpreting the data. Capturing that knowledge should not depend on an engineer translating every clarification into documentation.

Metadata visibility separates catalog browsing from access to the underlying data. With the appropriate metadata permissions, users can explore catalog information and lineage without receiving permission to query the data itself.

The new APPLY COMMENT privilege also gives administrators a targeted way to let stewards edit object and column descriptions without granting broader privileges such as MODIFY or OWNERSHIP.

This gives business experts a direct role in improving the context that people and AI workflows can use, while administrators retain control over data access. A clarification becomes reusable knowledge alongside the data, rather than an answer that stays in a chat thread or one agent's prompt.

Reduce the cost of maintaining useful context

An AI initiative needs context that teams can maintain, not just documentation prepared for its first demo. When the same customer identifier appears in multiple downstream views, repeatedly copying its description adds work without adding meaning. Missing or inconsistent descriptions leave both analysts and AI workflows with less context to work from.

Column description propagation uses column lineage to carry descriptions to supported downstream columns when their values pass through unchanged. For example, a description on a customer identifier can follow that column into a downstream view, even if the column is renamed.

Propagation stops when values are transformed, combined or aggregated, and it does not overwrite descriptions written directly on downstream columns. Teams can distinguish propagated descriptions from user-written ones. Once enabled, this reduces repetitive maintenance while keeping owners in control of meaning, so experts can focus on the definitions that need judgment.

For an AI-assisted retention analysis, context serves several purposes. Descriptions explain what customer fields represent. Lineage helps teams inspect where the data came from. A governed metric definition specifies how retention should be calculated. Each contributes something different to an answer people can evaluate.

People can explore context in Horizon Context. Snowflake CoCo can use catalog context for tasks such as data discovery and impact analysis. Semantic views complement that foundation with governed definitions of metrics, dimensions and relationships for AI and analytics.

The business value is reuse: Teams can build on shared knowledge rather than recreating it in each dashboard, application or prompt. That foundation supports more consistent interpretation and gives people evidence to examine when reviewing an AI-generated answer.

Put your business knowledge to work

Connect your supported data, BI and pipeline systems to Horizon Catalog. Bring business experts into description curation, and use Snowflake CoCo to explore lineage, investigate data issues and assess the impact of changes.

The knowledge your teams build today can become a reusable foundation for the next report, application and AI workflow.

Explore the supported connectors and setup documentation to get started.

Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
496b5a993c22234e1cb689a967816d22
Press Eligible
Yes
Press Eligible Reason
Snowflake announces enterprise data catalog and AI context capabilities for business users.
Source Name
Snowflake Newsroom
Original Summary

Horizon Context is in public preview with 18 metadata connectors, steward permissions and description propagation to ground AI in business context.

Image URL
https://www.snowflake.com/content/dam/snowflake-site/blog/general-stock-images/38-stock.jpg
Source Node
Content Hash (SHA-256, erste 32 hex)
f48ba2585149d63def81d5cc69a0a28d
Scaling Graph ML with NVIDIA Kumo on Snowflake ML
Image File
Original HTML

Enterprises run on relational data — customers connect to orders, orders connect to products, and transactions connect to accounts. These relationships, and how they change over time, encode the strongest signals about what will happen next.

Today, NVIDIA announced the Agent Knowledge Foundation, which provides open models and libraries that help enterprise agents retrieve the right evidence, apply consistent business meaning, predict outcomes, and optimize actions. As part of that announcement, NVIDIA also announced Kumo, a new family of open models, libraries and tools for predictive AI across structured data.

Snowflake customers can leverage the NVIDIA Kumo Relational model and NVIDIA Kumo Engine, an open-source package for training graph neural networks at scale across an enterprise’s full relational graph. Snowflake customers can install the Kumo package and run it on Snowflake ML, using Snowflake Notebooks on Container Runtime, so data science teams can build predictive models from the relationships in their data, with training, scoring and data all staying inside Snowflake's security and governance perimeter.

Vanja Josifovski, VP of Graph Engineering at NVIDIA, says, "Enterprise data is inherently relational, and the most accurate predictions come from learning on that structure directly rather than discarding it. With NVIDIA Kumo, Snowflake customers can harness graph neural networks on their connected data — tables, keys and temporal patterns — using NVIDIA GPU acceleration, all without moving data outside their governed environment. This is what predictive AI on enterprise data should look like."

How it works

Kumo learns directly from relational structure and temporal patterns — tables, the keys that connect them and the timing of events — rather than requiring teams to flatten rich connections into a single wide table. This applies across core enterprise prediction tasks: customer churn, fraud detection, demand forecasting and product recommendation.

For example, here's a snippet showing how a team might train a model to predict which active customers will buy again in the next 90 days, using four Snowflake tables and a few lines of Python in a Snowflake Notebook:

import kumo.engine as kumo

# 1. Build the graph

graph = kumo.Graph(

tables={"Customer": customer, "Product": product, "SalesOrderHeader": orders, "SalesOrderDetail": lines},

edges=[

kumo.Edge(src_table="SalesOrderHeader", fkey="CustomerID", dst_table="Customer"),

kumo.Edge(src_table="SalesOrderDetail", fkey="SalesOrderID", dst_table="SalesOrderHeader"),

kumo.Edge(src_table="SalesOrderDetail", fkey="ProductID", dst_table="Product"),

],

)

# 2. Write the predictive query

pquery = kumo.PredictiveQuery(graph=graph, query="""

PREDICT COUNT(SalesOrderHeader.*, 0, 90, days) > 0

FOR EACH Customer.CustomerID

WHERE COUNT(SalesOrderHeader.*, -365, 0, days) > 0

""")

# 3. Fit

model_plan = pquery.suggest_model_plan()

trainer = kumo.Trainer(model_plan)

train_job = trainer.fit(

graph=graph,

train_table=pquery.generate_training_table(non_blocking=True),

)

# 4. Batch predict and write the scores back to Snowflake

pred_job = trainer.predict(

graph=graph,

prediction_table=pquery.generate_prediction_table(non_blocking=True),

output_types={"predictions"},

output_connector=conn,

output_table_name="CUSTOMER_REPURCHASE_90D"

)

Customers install the Kumo package into a Snowflake Notebook and run it on Snowflake infrastructure:

- Snowflake Notebooks provide the development surface for connecting to governed data, defining prediction targets and reviewing results.

- GPU compute pools provide NVIDIA GPU infrastructure through Snowflake's container runtime, governed by the same controls as other Snowflake resources.

- NVIDIA’s verified agent skills for Snowflake CoCo accelerate getting started: Teams describe a prediction task in natural language and receive a runnable notebook, from data connection through GPU training to writing predictions back to Snowflake.

This ease of use also puts graph-based predictive modeling in the hands of many more users, increasing impact across the organization. Because Kumo runs inside the customer's Snowflake account, data never has to leave it. Kumo reads from Snowflake tables, trains on Snowflake compute pools and writes predictions back to Snowflake tables. Teams can orchestrate those workloads with Snowflake ML capabilities such as ML Jobs, all under Snowflake's existing security perimeter.

Customers are already seeing results

Customers like Affirm, National Oilwell Varco (NOV), VideoAmp, and Yieldmo are already benefiting from NVIDIA Kumo on Snowflake ML.

Lynn Steffen, VP of Finance Business Operations at NOV, says, “NVIDIA Kumo didn't just speed up our data science work; it changed the pace we thought was possible. At NOV, we've put it to work across very different areas of our business, and each time it's accelerated how quickly we can turn data into action.

CoCo has pushed that even further in Snowflake by removing friction between the data and the work, letting us explore, build and iterate where the data already lives.”

Craig Simmons, VP of Product at Yieldmo, says, "Buyers shouldn't have to choose between precision and scale. Companion Audiences builds act-alike audiences designed to perform. It learns from what's already driving results, extends traditional targeting and helps uncover new audiences buyers wouldn't have found otherwise. Buyers set the similarity threshold, decide whether Companion leads or backs up the campaign, and, for managed service buyers, can train directly from conversion data with no seed spend. NVIDIA Kumo running with Snowflake ML is built with privacy in mind."

Get started

To get started, check out the guide or explore the Snowflake ML documentation.

Class (B2B/B2C)
B2B
Ingest Status
Rewritten
Dedupe hash
ecb12420fc74154f57c7a442a2f3710e
Press Eligible
Yes
Press Eligible Reason
Manuelle Prüfung nötig. Risiko: MEDIUM. Flags: ['none']. Stichprobe: False
Source Name
Snowflake Newsroom
Original Summary

NVIDIA Kumo, now open source, runs on Snowflake ML so teams can train graph neural networks on relational data with GPUs, all inside Snowflake.

Image URL
https://www.snowflake.com/content/dam/snowflake-site/blog/general-stock-images/30-general.jpg
Source Node
Content Hash (SHA-256, erste 32 hex)
e1ca86da8115900df084752ac648f8c3